
What it is
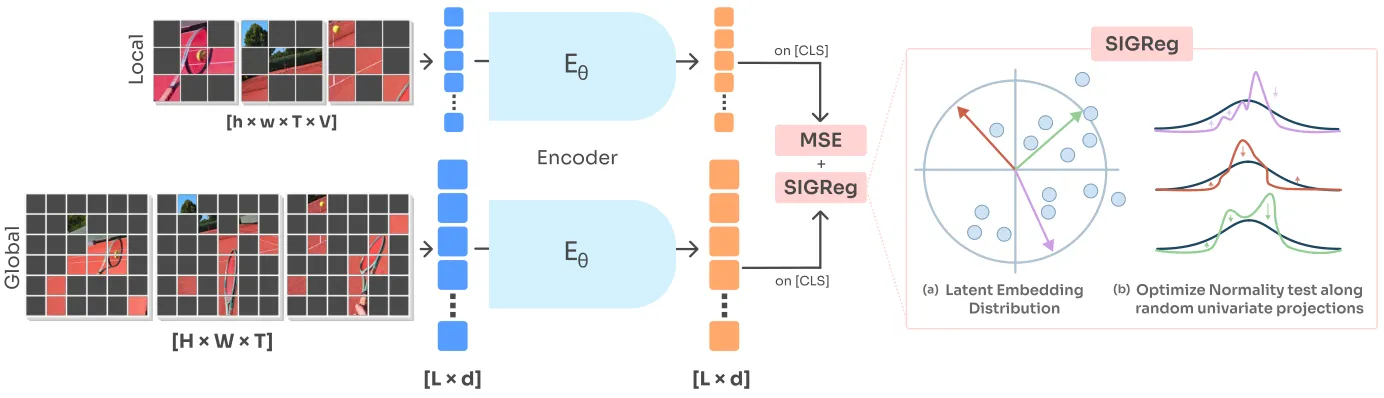
Self-supervised video pretraining with a single encoder and SIGReg, removing target encoders, predictors, and masking heuristics while cutting compute sharply. Pretrains video encoders without EMA targets, predictors, or reconstruction, using random token dropping and optional block-causal attention to learn frozen video features efficiently.
Key results
- Matches or beats V-JEPA 2 at 5.6-20.8× less total compute
- 95% random token drop improves ImageNet probe 33.9% to 47.6%
- Block-causal attention keeps accuracy: 51.2% vs 50.7% bidirectional
Shows collapse-free video pretraining can be simpler and substantially cheaper without the usual anti-collapse heuristics.