
What it is
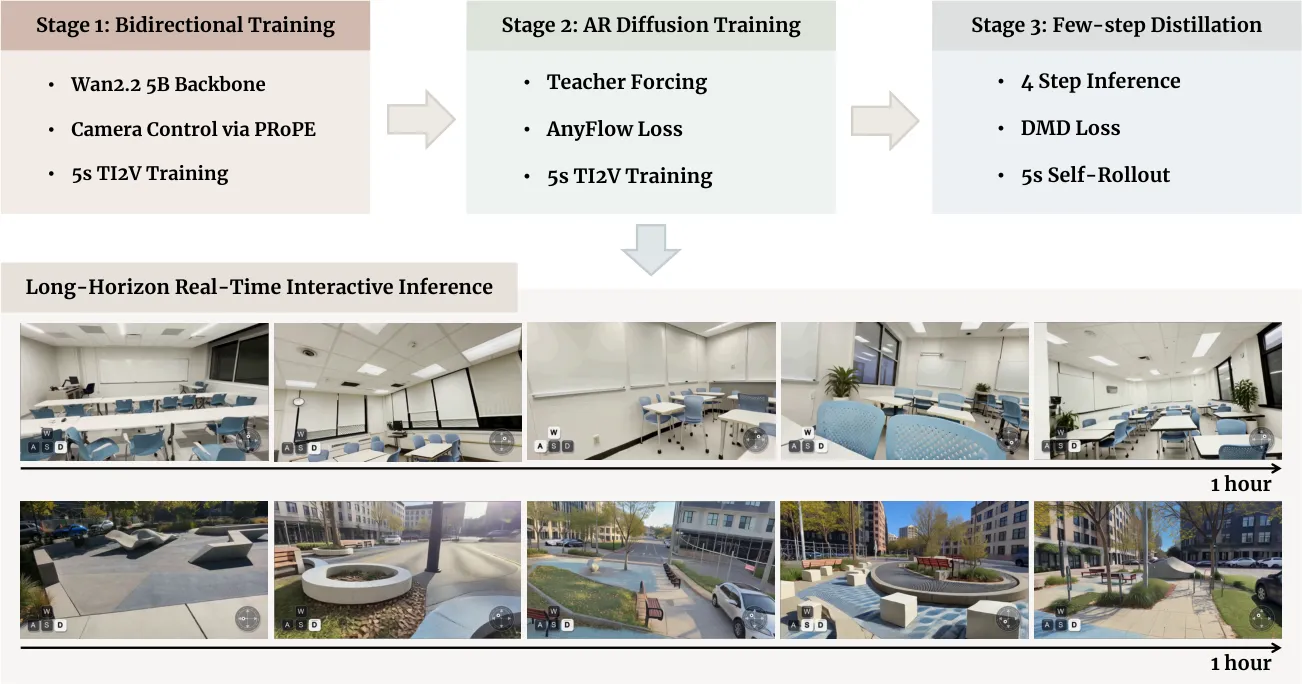
Open framework and dataset stack for training interactive long-horizon video world models across multiple video backbones with a shared 3-stage recipe. Instead of model-specific pipelines and naive dataset mixing, it standardizes 10 video sources into one training contract and adapts diverse backbones with a shared 3-stage causal recipe while keeping native objectives.
Key results
- 4 released models span 5B to 33B across 3 backbone families
- 1.43M canonical clips from 10 datasets, totaling 25.85 TB
- Minutes-to-hours real-time rollouts after training only on 5s sequences
Long-horizon interactive rollout can emerge from short-sequence training when data standardization and causal adaptation are aligned across backbones.