
What it is
Streams monocular 3D reconstruction over long videos using only a fixed 12-frame context, then composes local geometry and adjacent poses into a global map. Reconstructs long image streams in one causal pass, predicting per-frame local point maps and adjacent poses, then composing them into a global trajectory and point cloud with optional loop-closure refinement.
Key results
- Fixed 12-frame local context; no persistent learned long-range memory
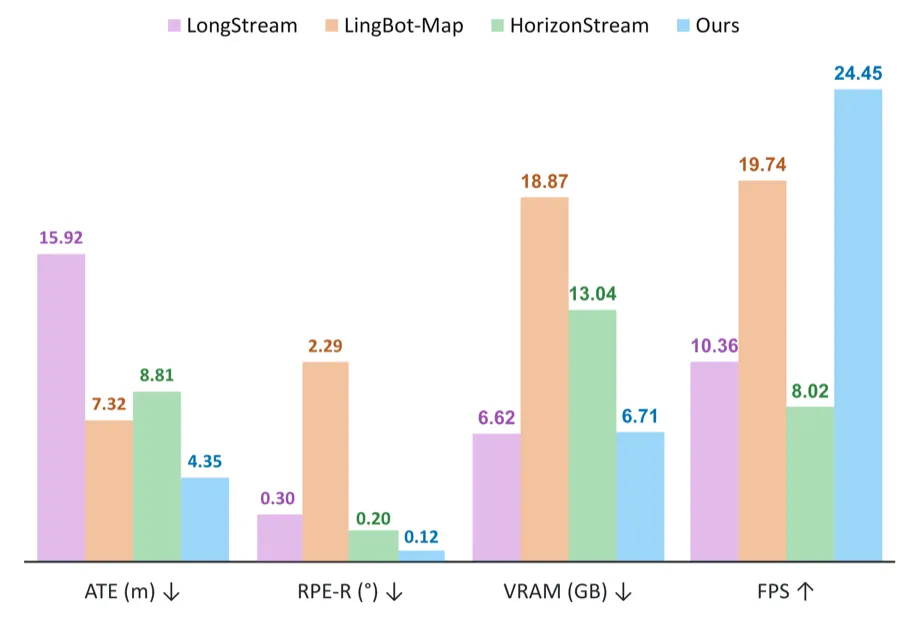
- 24.45 FPS and 6.71 GiB on KITTI-02 at 504×280 on NVIDIA H100
- Oxford Spires: 4.35 m ATE, 0.12° RPE-R, 91.81% F1 dense recon
Shows long-horizon streaming reconstruction can be done with bounded local context plus pose composition, without learned long-range memory.