
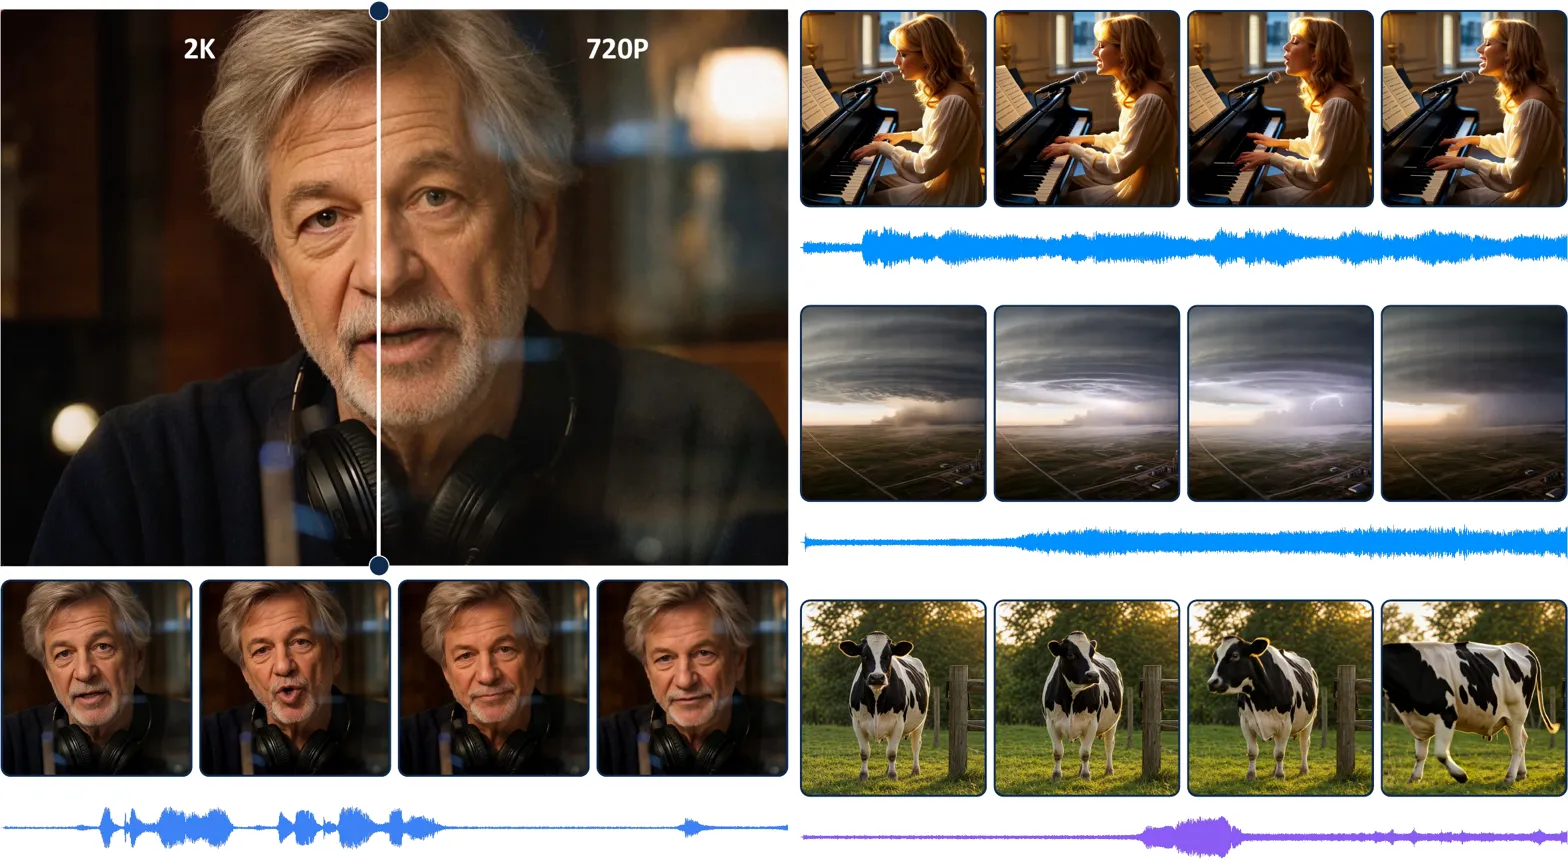
What it is
Framework for native joint audio-video generation from a first frame and prompt, plus a 1-step refiner that upgrades outputs to 2K video. Generate synchronized video with audio from a first frame and text prompt, then refine the result or any input video to 2K with a separate 1-step super-resolution model.
Key results
- Ships a 7B joint audio-video generator with released weights
- Includes an autoregressive 1-step 2K refiner based on SR-DiT 5B
- Supports single-GPU inference and multi-GPU sequence-parallel runs
Shows that open native joint audio-video generation can be packaged with a practical 2K refinement stage.