Dataset

XL-DocBench

Contains 1,345 expert-verified QA records over 292 long professional documents, with page-level evidence for single-doc and cross-doc QA.

Hugging Face ↗Sep 2, 2026Paper ↗

  • nlp
  • cv
  • multimodal
  • document-understanding
  • cross-document-qa
  • long-context
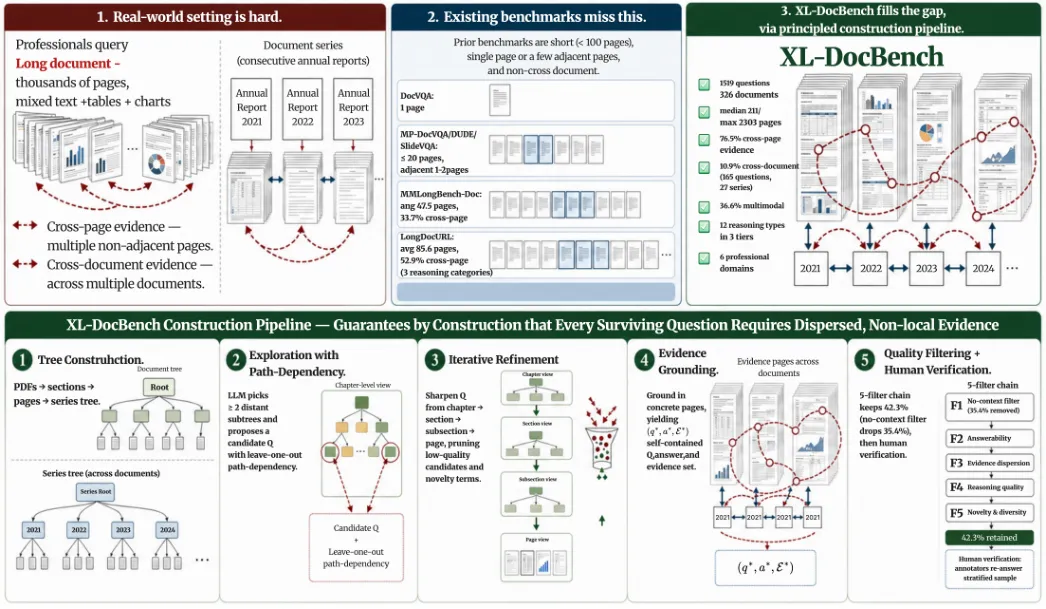
Comprehensive figure showing motivation, benchmark stats, and construction pipeline for dataset

What it is

Expert-verified benchmark for evidence-grounded QA over very long professional documents, including cross-document and abstention cases. 1,345 expert-verified QA items over 292 public documents, split into 1,191 single-doc and 154 cross-doc questions, with page-level evidence, multimodal support, abstention cases, and per-question scores for 13 systems.

Key results

  • 1,345 total questions: 1,191 single-doc + 154 cross-doc
  • 292 documents from 6 professional domains
  • 429 multimodal-evidence questions; 188 require None answers

Useful for benchmarking evidence-grounded long-context document QA with retrieval, reasoning, and abstention.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.