
What it is
Learns robot world-action models from large-scale egocentric video, then grounds them with cross-robot trajectories and deploys them with a real-time Slow-Fast controller. Instead of learning control only from costly action-labeled robot data, pretrains a causal world-action model on 120k+ hours of embodied video, then aligns it to heterogeneous robots via a unified action space and runs it with an asynchronous Slow-Fast controller.
Key results
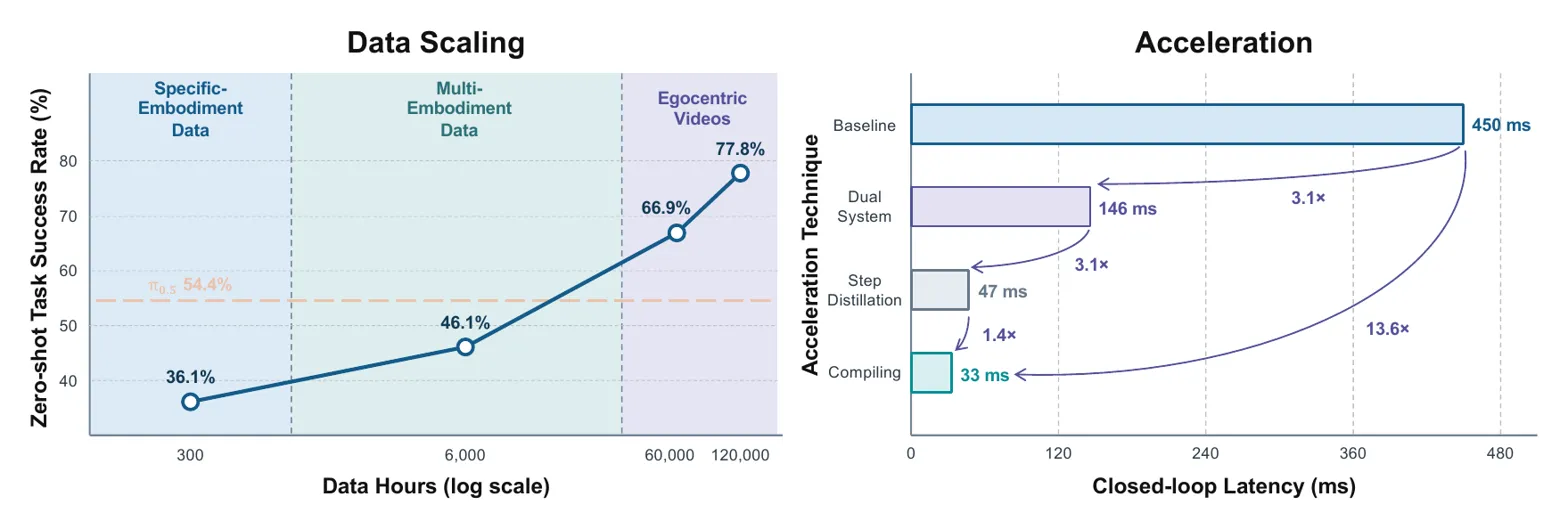
- 77.8% zero-shot success with 120k h video vs 36.1% target-robot only
- 66.9% zero-shot success with 60k h video vs 46.1% with multi-robot data
- Closed-loop latency drops from 450 ms to 33 ms, enabling 30 Hz control
Large-scale embodied video is an effective scaling axis for robot generalization when paired with action grounding and a fast execution path.