
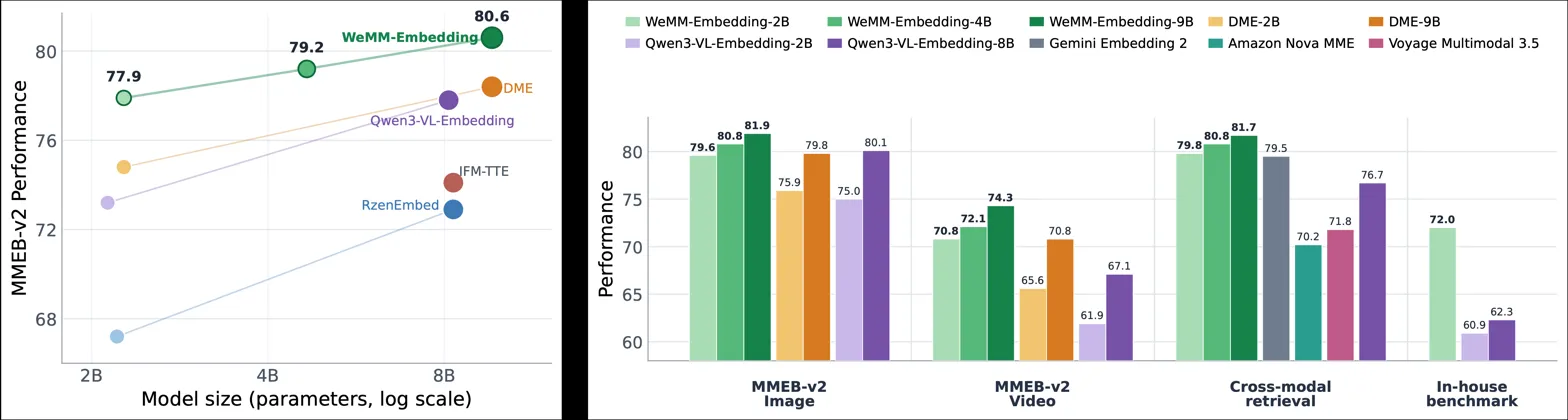
What it is
Universal multimodal embedding models for text, images, videos, visual documents, and interleaved inputs, with SOTA results on MMEB-v2 and MMEB-v3. Generate a single embedding space for text, images, videos, visual documents, and interleaved multimodal inputs, with selectable Matryoshka dimensions for smaller vectors.
Key results
- MMEB-v2: 2B scores 77.9 avg, ahead of Qwen3-VL-Embedding 2B at 73.2
- MMEB-v3: 9B scores 59.5 overall vs Qwen3-VL-Embedding 8B at 53.5
- 2B at 256 dims retains 98.7% of full image/video performance on MMEB-v2
Shows one embedding model can cover text, image, video, and visual-document retrieval without giving up top benchmark performance.