
What it is
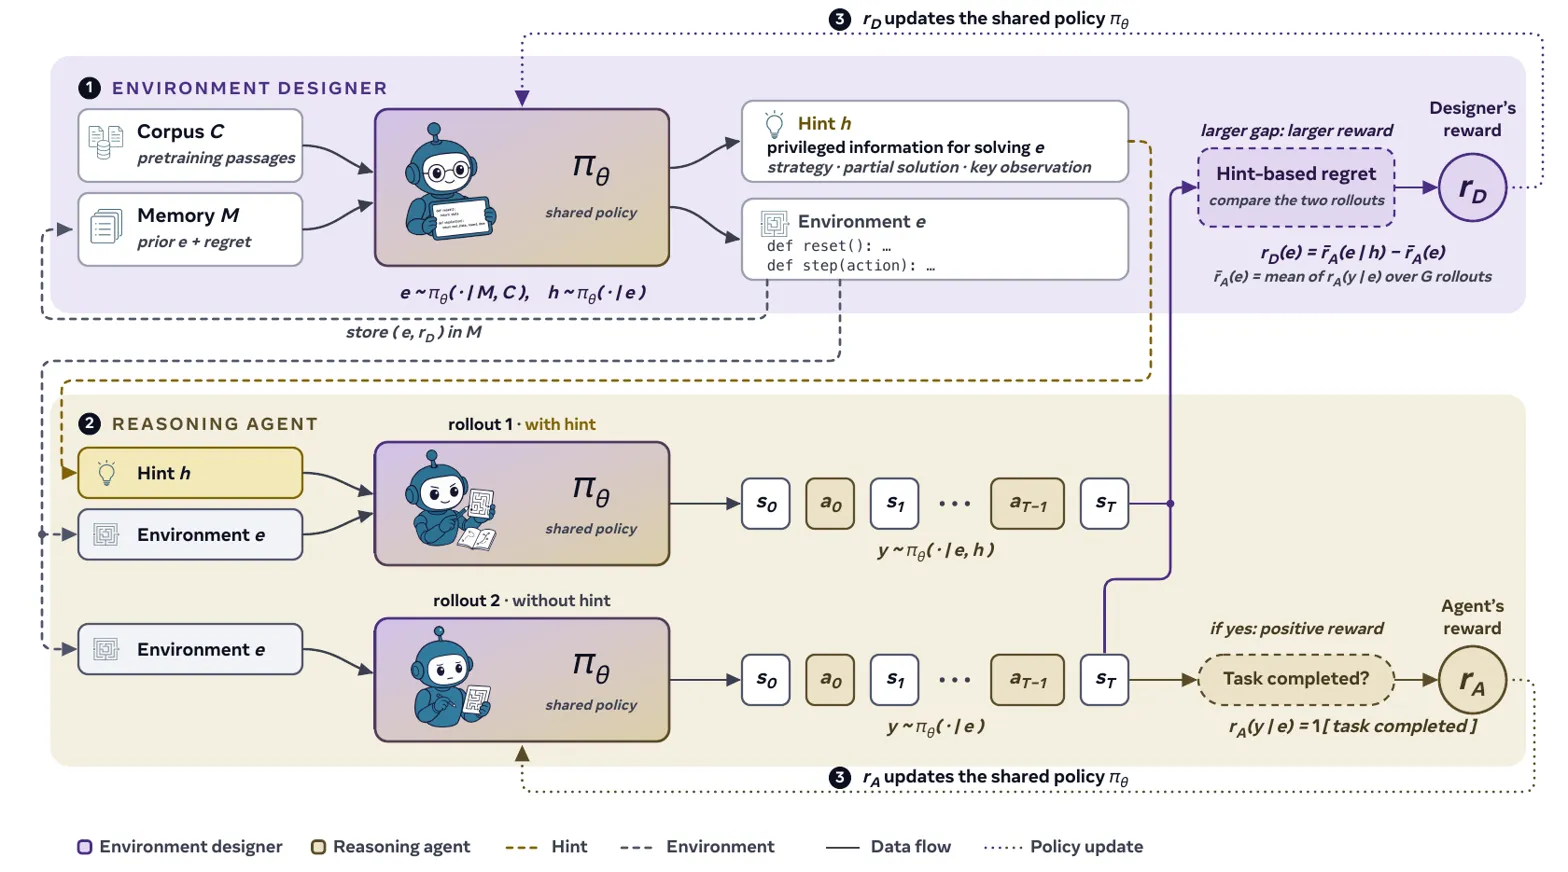
A single LLM learns both to write executable training environments and solve them, creating an adaptive self-play curriculum for reasoning and tool use. Instead of training on fixed task pools or frozen generators, the model learns an Environment Designer that writes full Gym-style executable environments and a solver that acts in them; designer reward is the solve gap with vs. without privileged hints, pushing tasks to the agent's capability frontier.
Key results
- +13.9 on ACEBench-Agent over the strongest fixed-env baseline at 30B
- +5.7 on BFCL v4 multi-turn at 30B over the strongest fixed-env baseline
- +5.3 avg across 8 held-out math/science/code/reasoning evals at 30B
Training the environment generator itself, rather than keeping the task pool fixed, yields stronger transfer as the agent scales.