Repo

apex-inference-chip

Implements a verified FPGA LLM inference tile that runs one decoder layer and compresses KV cache in the attention datapath.

GitHub ↗Aug 17, 2026

  • llm
  • fpga
  • kv-cache
  • rtl
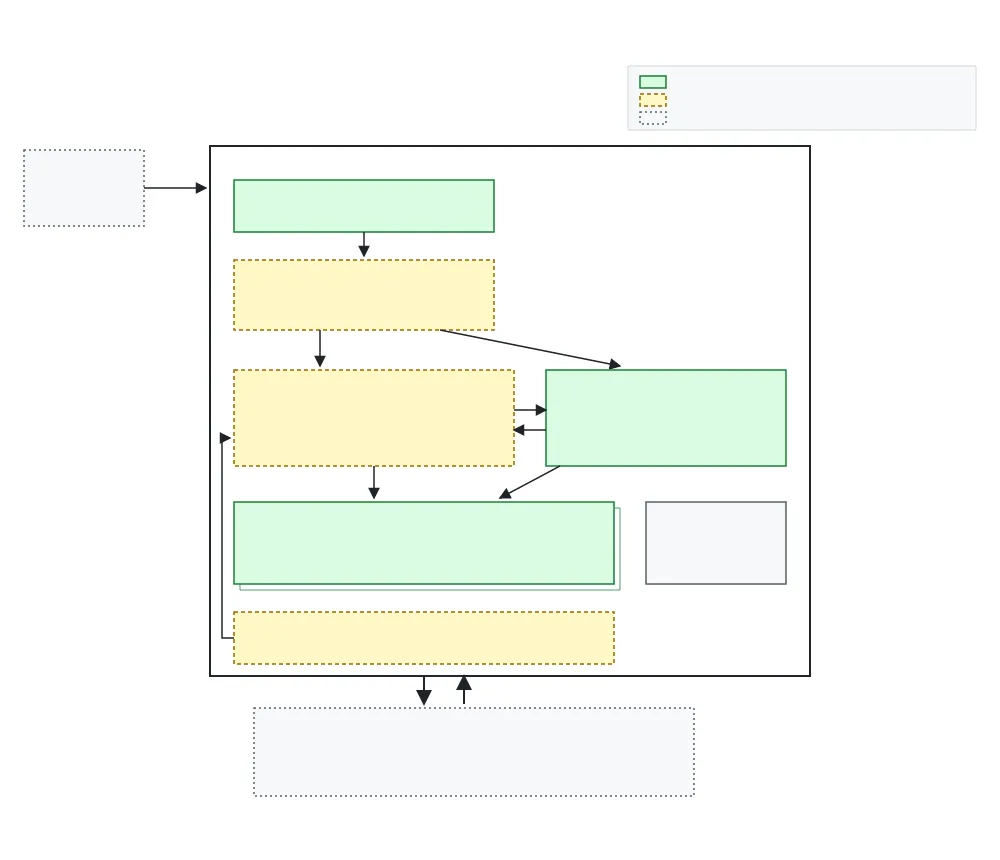
Block diagram with data flow showing system pipeline architecture and components

What it is

Open RTL for one verified LLM decoder layer on FPGA, with in-datapath KV-cache compression and bit-exact checks against a golden model. Run a real transformer decoder layer on FPGA with compressed KV cache stored and read in hardware, while replaying Qwen jobs bit-exactly against an executable golden model.

Key results

  • 0.56 tok/s measured on FPGA; 140× over 0.004 tok/s baseline
  • Bit-exact RTL vs NumPy golden model across blocks and full layer
  • Runs Qwen2.5-0.5B on FPGA; 7B tokens replayed in verified pipeline

Shows that open, bit-exact RTL for real LLM decoder-layer inference with in-datapath KV compression is practical on FPGA.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.