
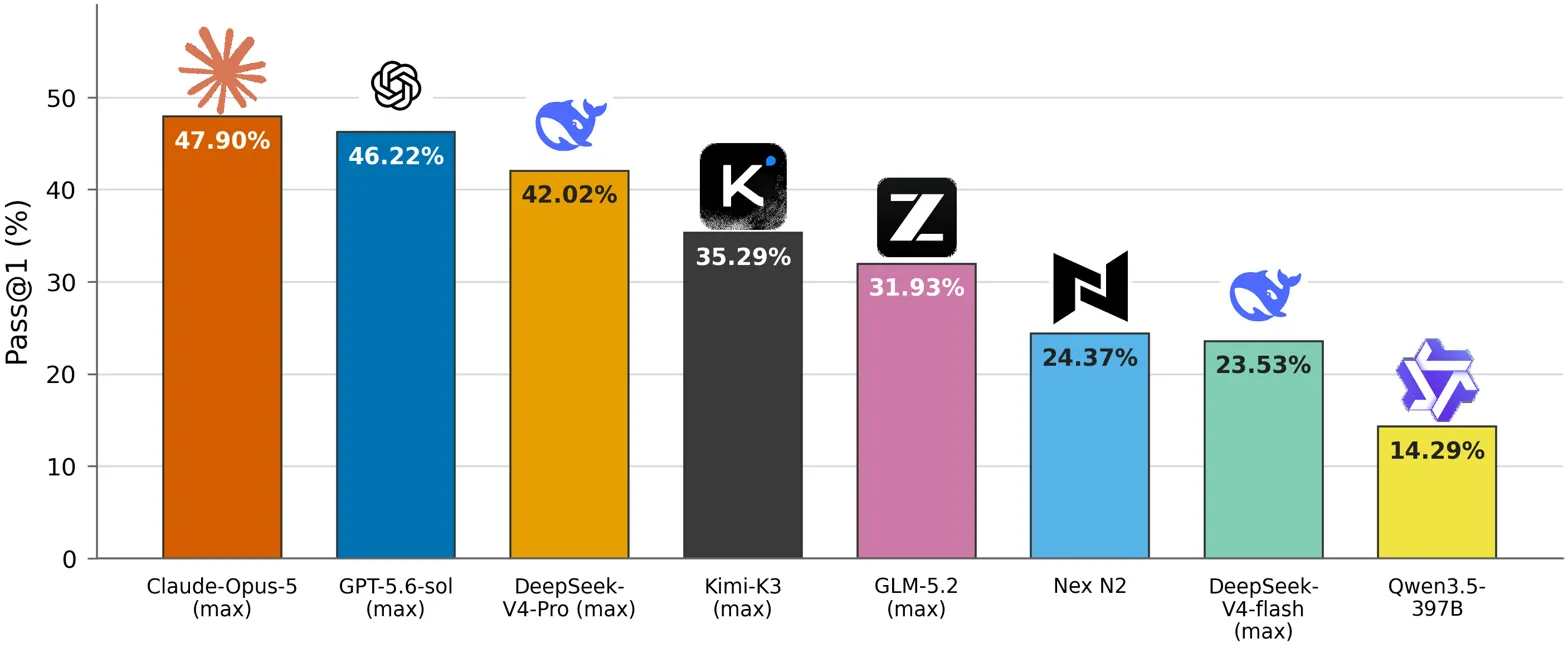
What it is
Benchmark dataset for evaluating coding agents on scientific software-engineering tasks with isolated runtimes and separate verifiers. 119 text-defined coding tasks across 20 scientific domains, each paired with a pinned runtime Docker image and a separate verifier image; released as CSV/JSONL Harbor/Pier task bundles.
Key results
- 119 tasks across 20 scientific domains
- 96 unrestricted tasks + 23 restricted-license tasks
- 119 runtime images and 119 verifier images, linux/amd64
Useful for benchmarking coding agents on long-horizon bug-fixing and implementation tasks in scientific codebases.