
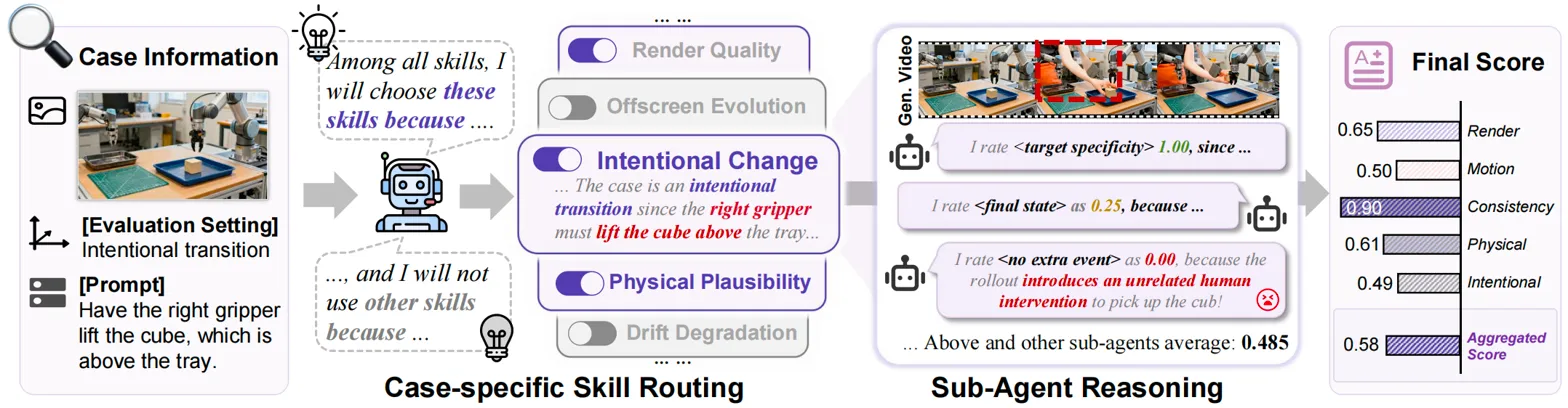
What it is
Agent-based benchmark for world-model video evaluation that produces auditable reasoning traces instead of only scalar scores. Evaluates generated world-model videos with case-specific skill routing, sub-agent checks, and auditable evidence trees that justify each case score.
Key results
- Writes summary.json, CSV/JSON leaderboards, and LEADERBOARD.md
- Saves full case traces under model outputs and metric_cache
- Routes by case context only, not by the model being evaluated
Shows that world-model benchmarking can be automated with inspectable reasoning rather than opaque aggregate metrics.