
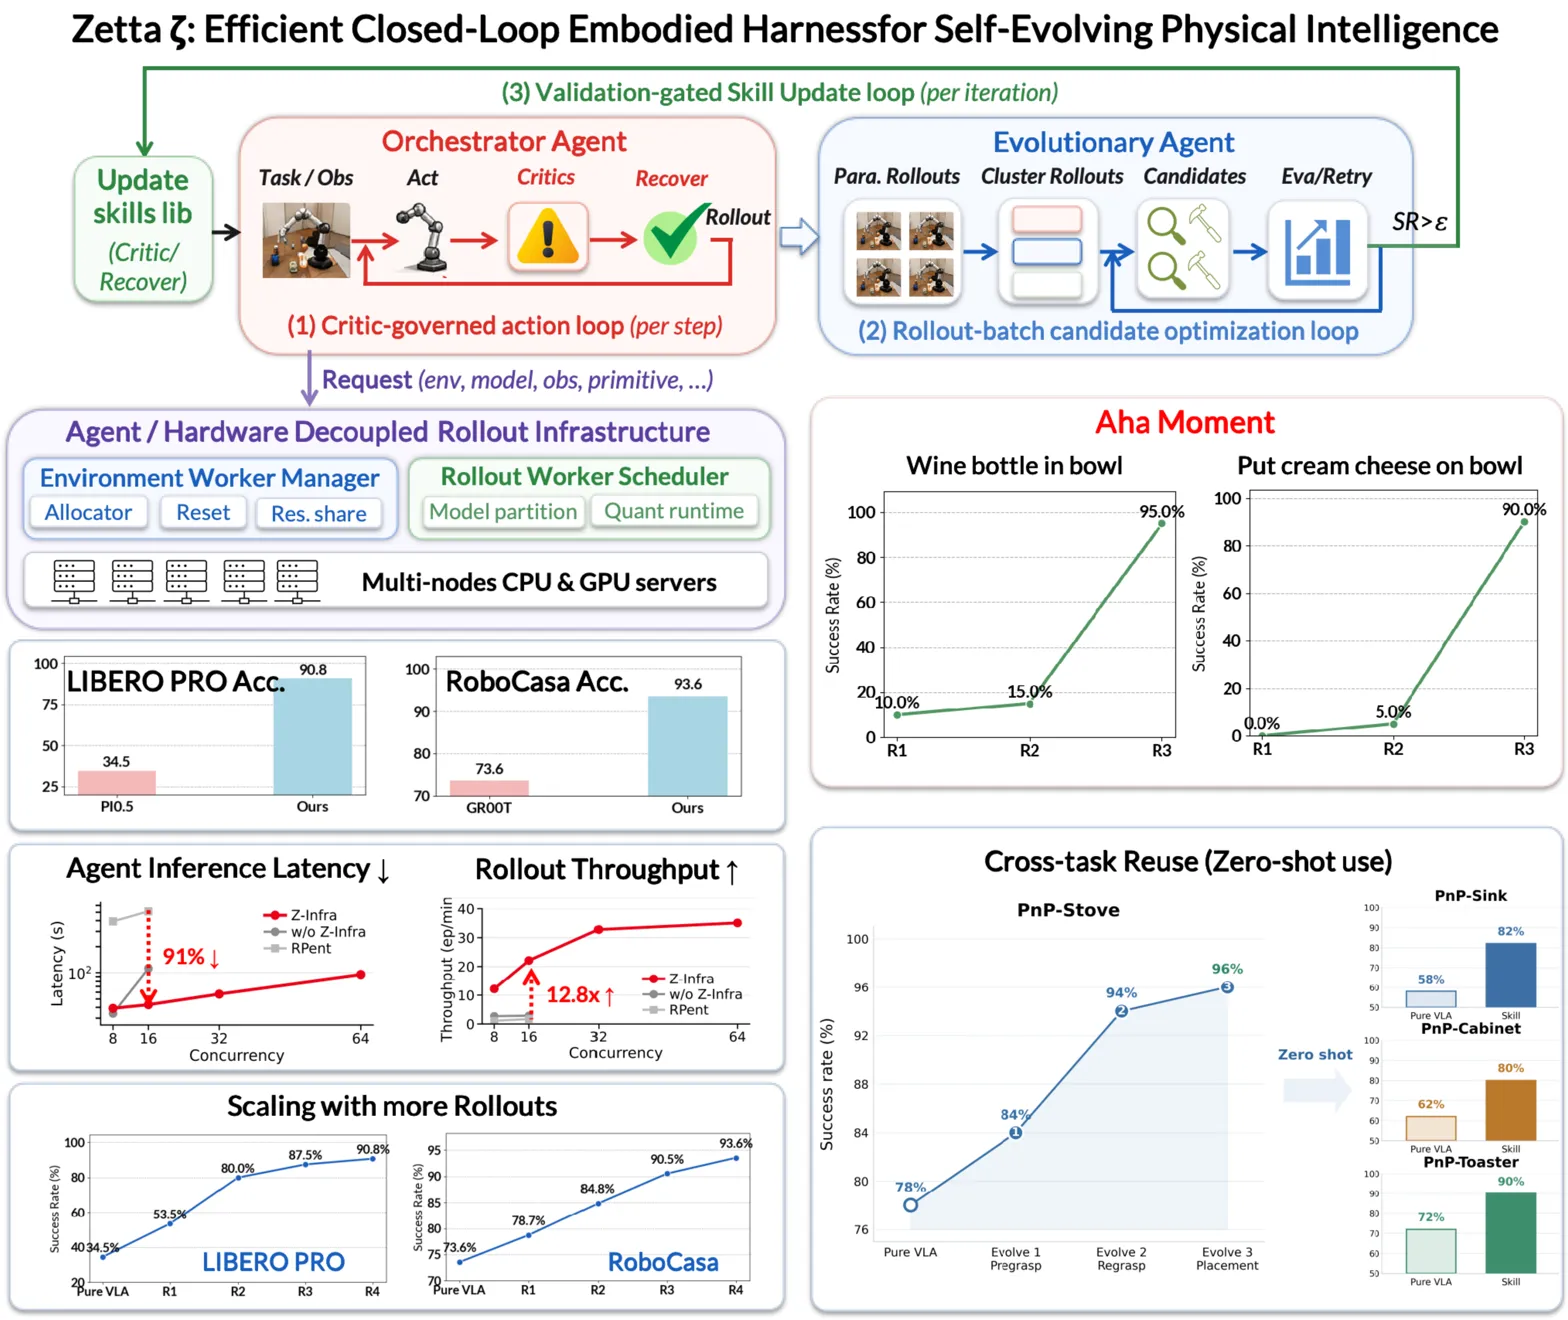
What it is
A closed-loop embodied harness that keeps the base robot policy frozen and learns runtime critics plus recovery skills online for self-improving execution. Instead of post-hoc reflection after rollouts, it adds action-frequency code critics that trigger recoveries during execution, then validates and distills failures into reusable skills while leaving the base policy frozen.
Key results
- 90.8% success on LIBERO-Pro under current rollout budget
- 93.6% success on RoboCasa under current rollout budget
- 11.1x faster inference than RPent; throughput rises 1.7 to 35.1 eps/min
Shows frozen robot policies can gain large reliability improvements by evolving a closed-loop execution harness around them.