Paper

UI-Mate: Advancing Open-Weight Foundation GUI Agents with In-Context Demonstrations

Rather than replay demo trajectories, it uses demos as subtask guidance while re-planning from live pixels, trained with a closed-loop executable GUI data stack.

arXiv ↗Aug 16, 2026Code ↗

  • multimodal
  • gui agents
  • in-context learning
  • reinforcement learning
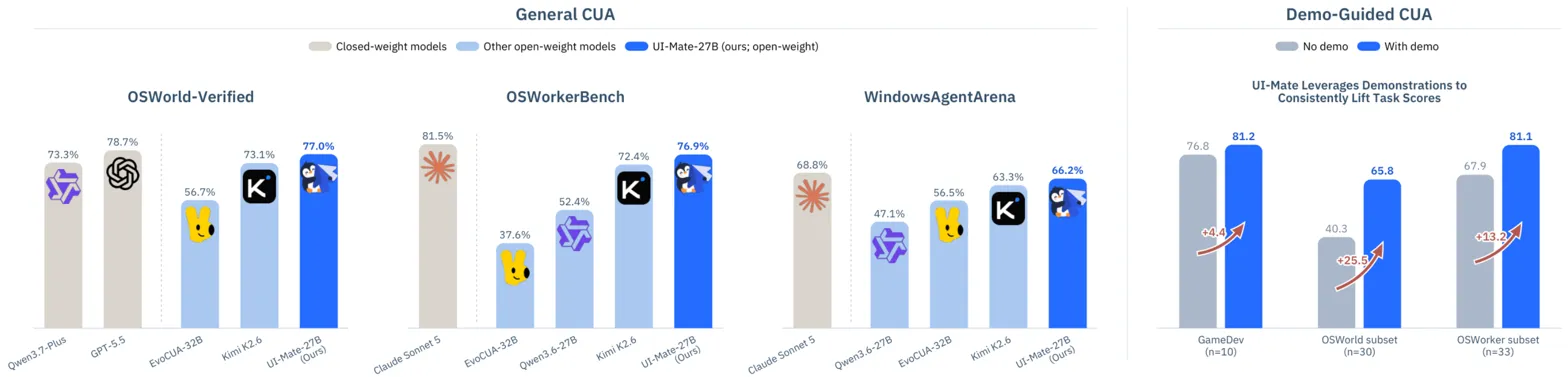
Bar charts comparing method vs baselines across multiple benchmarks; headline results

What it is

An open-weight GUI agent that pairs environment-grounded training with in-context demonstrations to improve long-horizon desktop task execution and reliability. Instead of relying on instruction-only prompts or replaying demos, it learns from executable GUI environments and turns multimodal demonstrations into adaptive subtask workflows grounded on the live screen.

Key results

  • 77.0% on OSWorld-Verified, best among compared open-weight agents
  • 66.2% on WindowsAgentArena, above Qwen3.6-27B's 47.1%
  • OSWorker self-demo strict success rises 17.2%→35.4% with one demo

Shows that grounding demonstrations as flexible workflow priors, not scripts, materially improves reliability on underspecified long-horizon GUI tasks.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.