Paper

StudentSim: Training LLM-based Student Simulators

A two-stage training setup turns sparse learner records into per-student simulators that both imitate the student and revise answers from tutor guidance.

arXiv ↗Sep 1, 2026Code ↗

  • nlp
  • user simulation
  • personalization
  • education
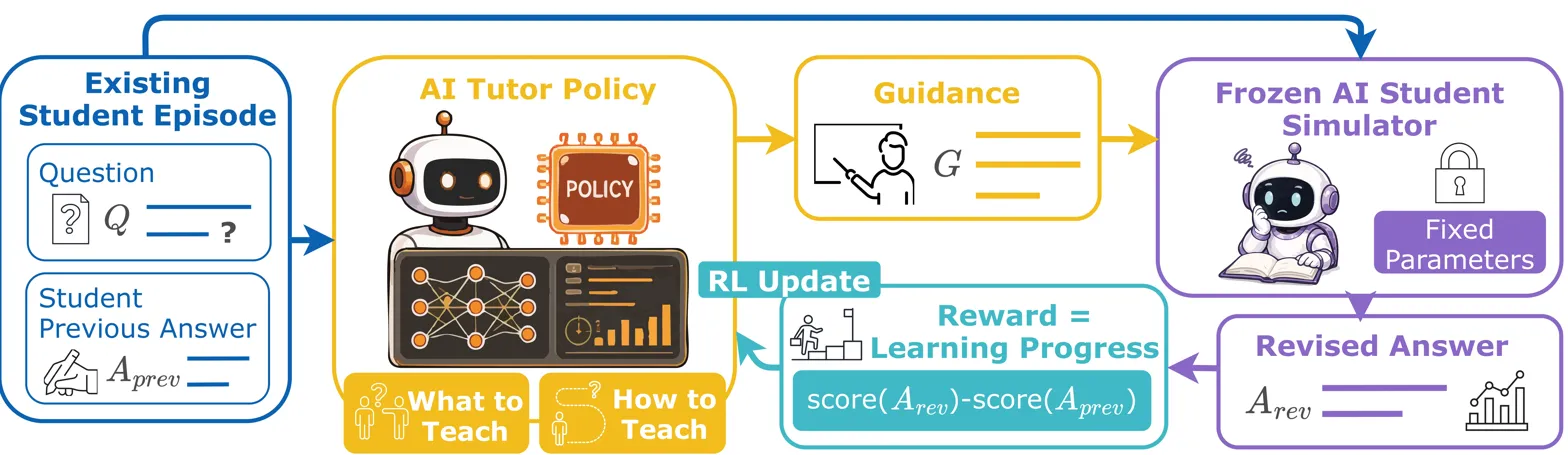
Pipeline diagram showing AI tutor RL loop with student simulator and reward

What it is

Builds per-student LLM simulators from sparse learner data via pooled pretraining plus student-specific tuning, and evaluates them on fidelity and response to tutor guidance. Unlike prompted LLM role-play or state-tracking models that get only one axis right, it trains individualized simulators with pooled domain training then per-student specialization to match a student's behavior and update under tutor guidance.

Key results

  • Chess: F=0.51, R=0.91 vs GPT-5.4's 0.23, 0.72
  • Chess: beats Maia2 on both axes, 0.51/0.91 vs 0.45/0.27
  • RL tutor using StudentSim reward was rated above no-RL and GPT-5.4-reward RL

Training on real learner records with shared pretraining plus per-student tuning can jointly recover student fidelity and teachability.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.