
What it is
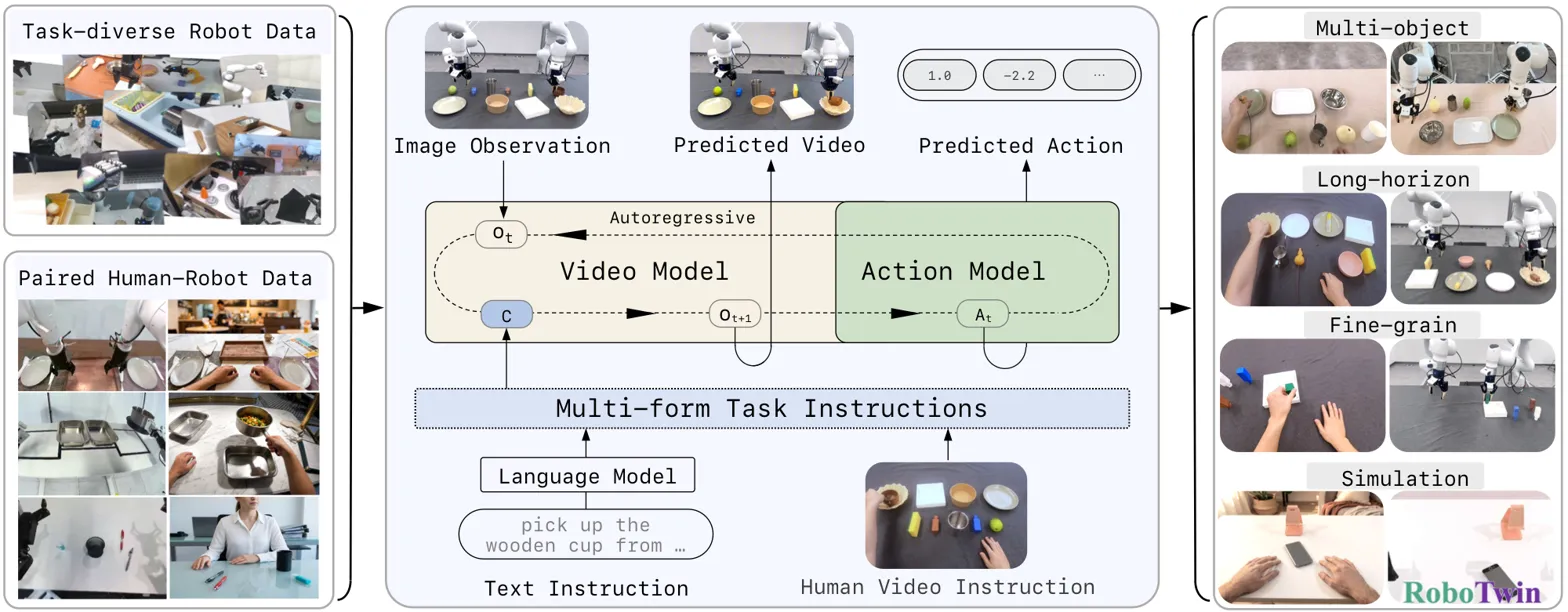
A robot video-action model uses human videos as in-context task prompts to execute unseen manipulation tasks without finetuning. Instead of relying on underspecified language, it conditions a causal video-action policy on human demo videos as task prompts. It scales this with auto-generated human-robot pairs and an IFP loss that forces use of the video context on unseen tasks.
Key results
- 47.0% avg success on 7 unseen RoboTwin tasks, +29.5 pts vs best baseline
- HumanGen provides 74.2K human-robot pairs spanning 8.6K tasks
- Beats LingBot-VA on all 3 real-world unseen task families
Shows that human video prompts can specify unseen manipulation tasks better than language-only conditioning for zero-shot generalization.