
What it is
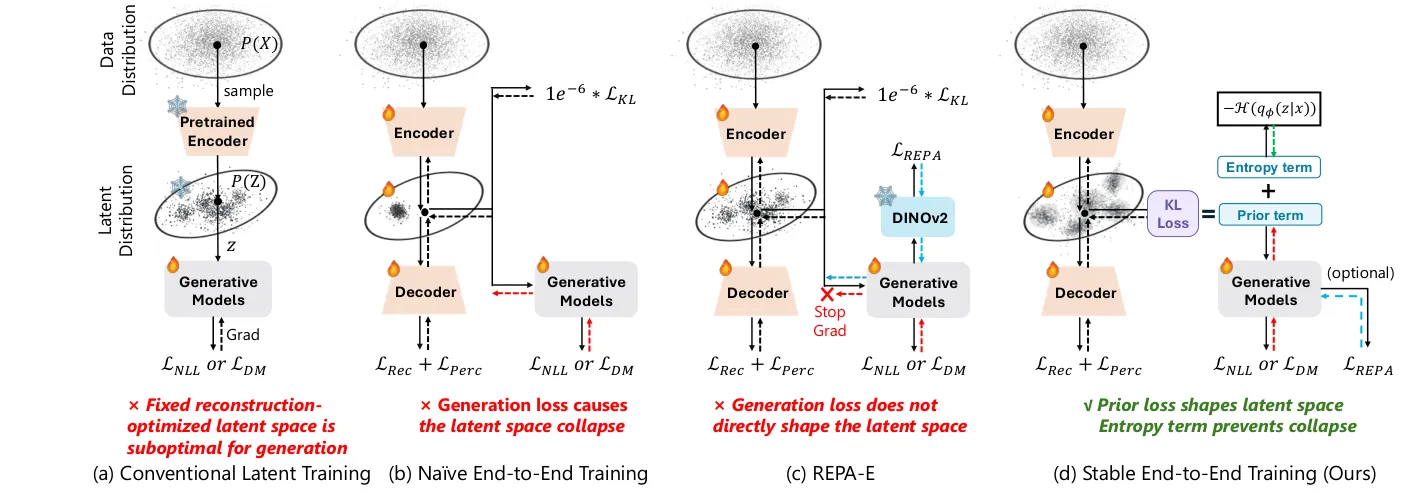
Enables direct end-to-end training of VAEs and latent priors without collapse by preserving posterior entropy and letting generation shape latents before reconstruction. Instead of freezing reconstruction-first latents or blocking generative gradients, it directly trains VAE+prior end to end with explicit posterior entropy and a generation-first schedule so the prior shapes a generation-friendly latent space before reconstruction tightens.
Key results
- ImageNet-256: gFID 0.97 with CFG using SiT
- ImageNet-256: gFID 1.45 without CFG using SiT
- Text-to-image: MMDiT reaches 0.90 GenEval
Shows stable direct end-to-end latent learning is feasible when entropy counters prior pressure and generation shapes the latent space early.