
What it is
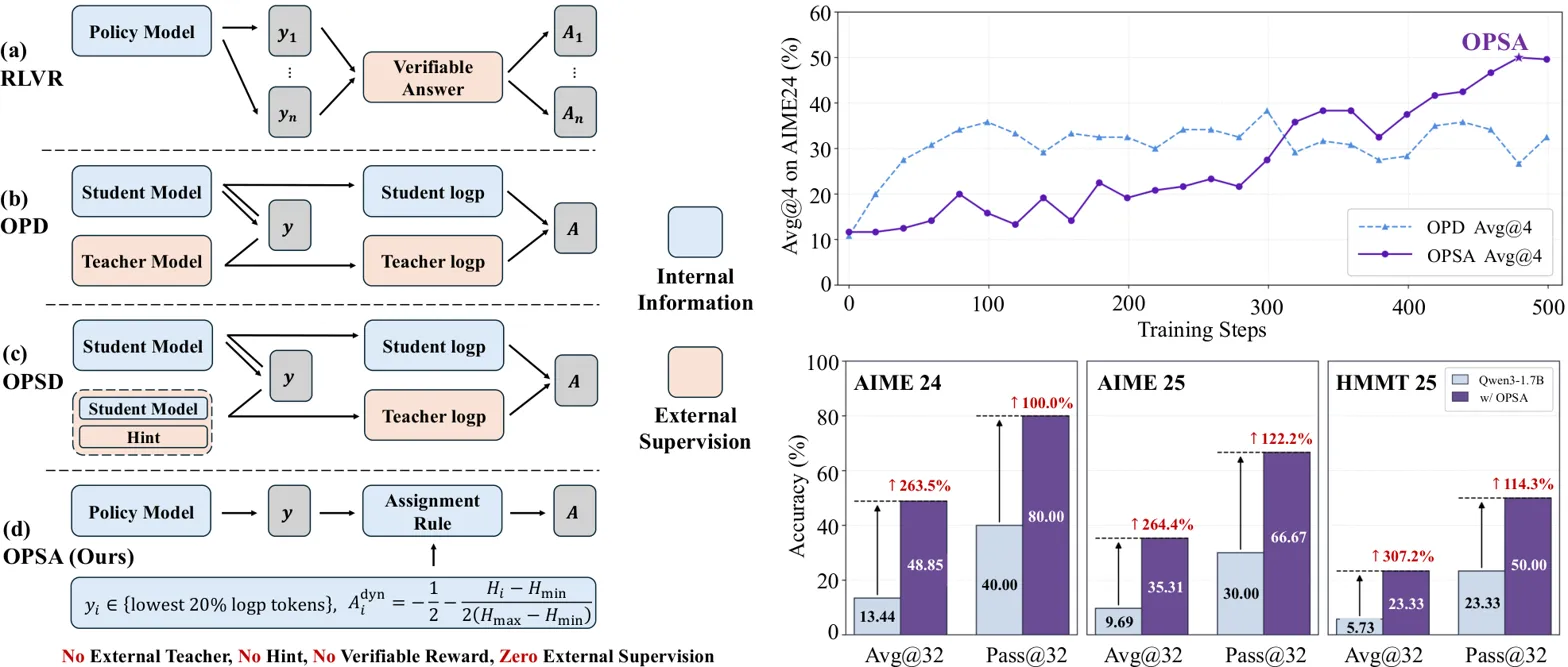
Questions whether on-policy distillation really transfers teacher knowledge, then replaces it with a teacher-free token-level RL rule using entropy-scaled negative updates on low-prob tokens. Instead of relying on noisy teacher token advantages in OPD, it learns by penalizing the student's own low-probability tokens; OPSA removes the teacher entirely and scales negative updates by token entropy.
Key results
- AIME24 Avg@32: +35.41 over base Qwen3-1.7B; 263% relative gain
- Beats OPD by 16.77 Avg@32 on AIME24
- More than doubles Pass@32 on AIME24, AIME25, and HMMT25
Shows OPD gains come largely from suppressing low-probability student tokens, not from reliable teacher distillation.