Paper

Self-OPD: On-Policy Distillation for Flow Matching Models without Teacher

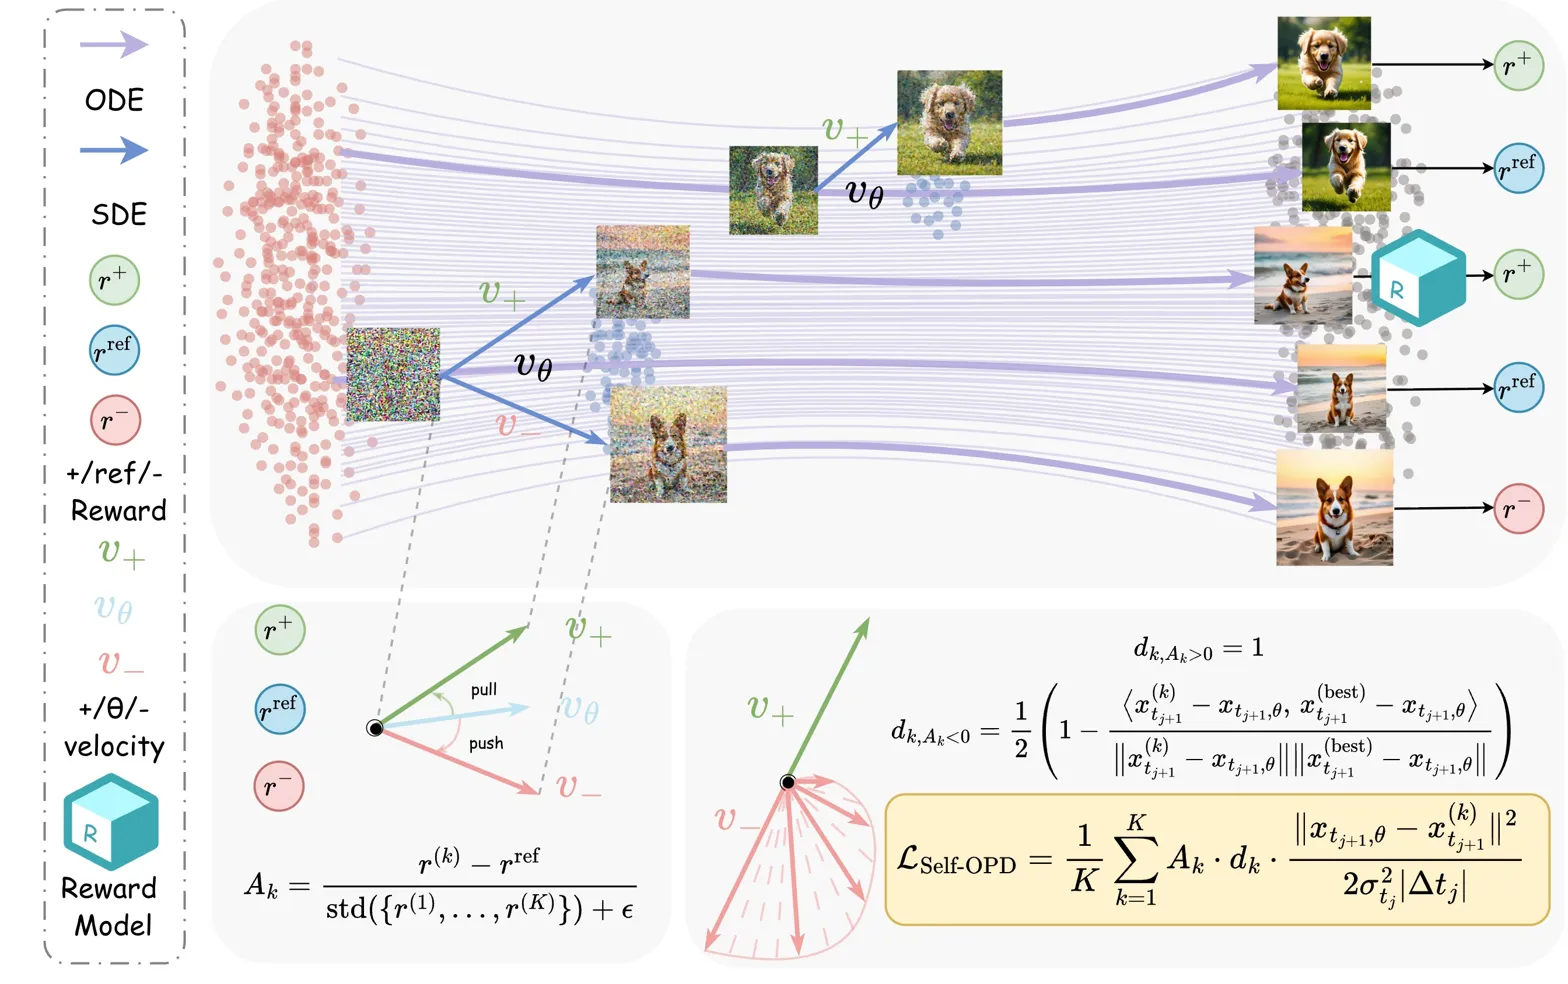
Teacher-free OPD for flow models: branch local SDE candidates from the student's step, score them, then use advantage-weighted pull-push distillation.

arXiv ↗Aug 27, 2026Code ↗

  • cv
  • flow matching
  • text-to-image
  • reward alignment
Method pipeline diagram showing reward-guided velocity optimization with loss equations and workflow

What it is

Teacher-free on-policy distillation for flow matching that turns the model's own local SDE exploration into dense per-step reward supervision. Instead of distilling from a task-specific teacher, it distills from the student's own branched SDE rollouts: better-rewarded branches pull the velocity field, worse ones push it away, with reward-level fusion for multi-objective alignment.

Key results

  • Beats prior RL methods on single-reward benchmarks
  • Beats teacher-based OPD on mixed-reward benchmarks
  • Needs no task-specific teacher while keeping dense per-step supervision

Dense on-policy supervision can be recovered from the student's own local exploration, avoiding teacher cost and teacher-student mismatch.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.