
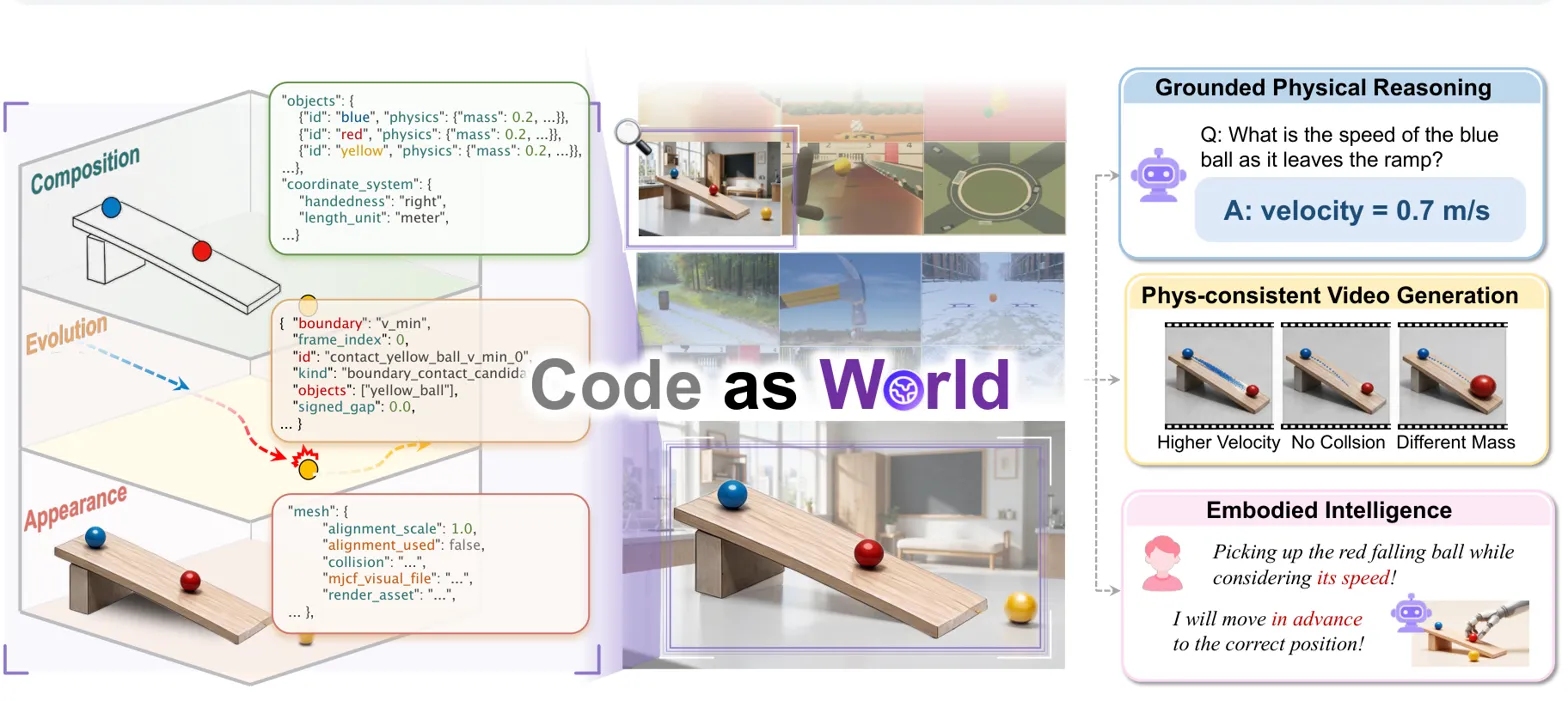
What it is
Represents physical scenes as executable code and discovers these world models from text or video via an agentic propose-execute-verify loop. Instead of pixels, 3D latents, or language alone, it uses executable code as the world model. An agent iteratively proposes, simulates, renders, and verifies code hypotheses, then uses verified worlds as scalable supervision for VLM physical reasoning.
Key results
- SOTA on QuantiPhy with Code-as-World-VL
- 9B model beats larger models, including Gemini-3.1-Flash, on QuantiPhy
- 27B model outperforms the 9B variant and all evaluated baselines
Explicit executable world models can provide scalable physical supervision that improves quantitative reasoning beyond larger black-box VLMs.