
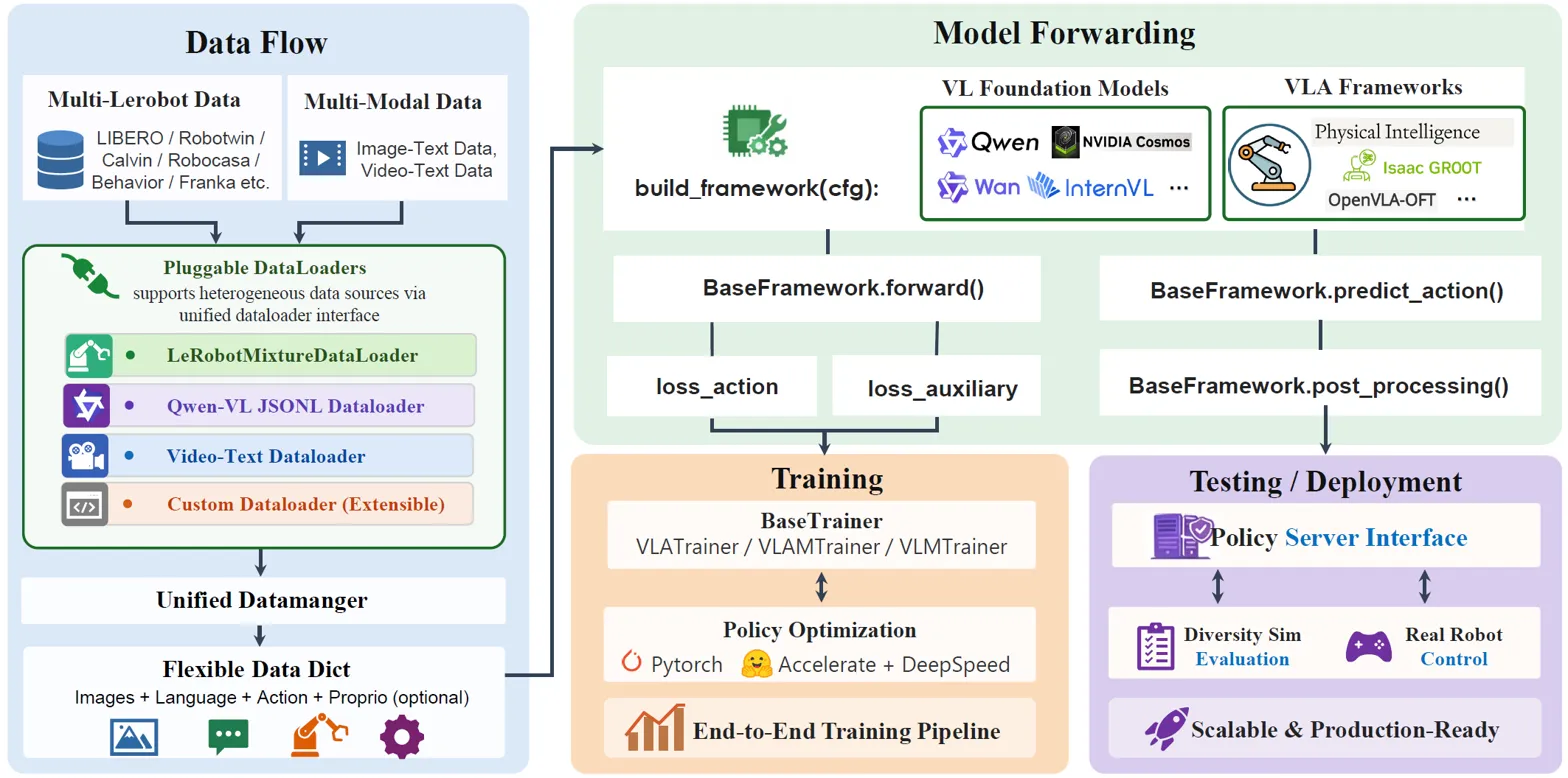
What it is
Continued pre-training for VLA backbones that preserves VLM priors and learns head-agnostic, cross-embodiment action representations from limited robot data. Instead of scaling trajectories or fitting one policy head, it shapes the VLM backbone for transfer: preserve VLM priors, co-train with multiple continuous action heads, and partially unify action spaces across embodiments.
Key results
- RoboCasa-GR1: 49.5% with 20% data vs GR00T-N1.6 full-data 47.6%
- RoboTwin 2.0: 92.5% success, beating ABot-M0 and LingBot-VLA
- LIBERO-Plus: 82.6% success; backbone-only gains are 7.6-21.4 pts
Shows backbone representation quality is an independent lever for VLA performance and transfer beyond simply collecting more robot data.