Paper

Self-Supervised Visual On-Policy Distillation

Creates on-policy distillation signal by degrading only the student's image view; an EMA teacher sees the clean image and supervises token predictions.

arXiv ↗Aug 14, 2026

  • multimodal
  • knowledge distillation
  • vision-language models
  • self-supervised learning
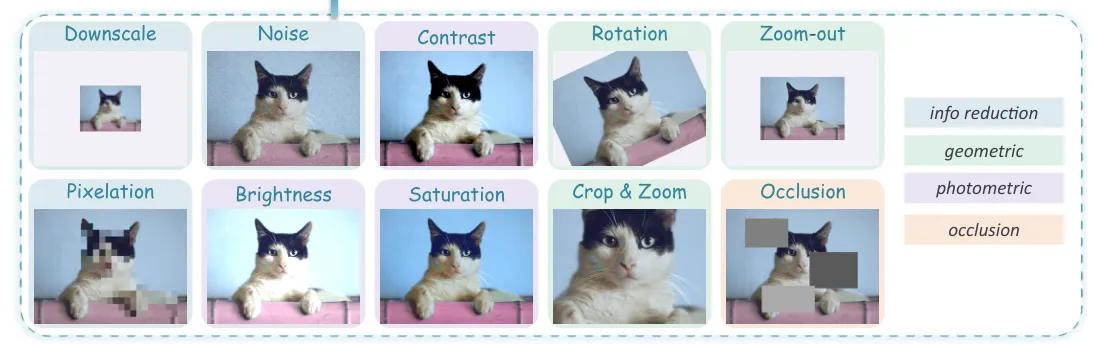
Composite showing categorized image augmentation types with taxonomy, illustrates dataset transformations

What it is

Self-distillation for VLMs without labels or stronger teachers: the teacher sees the clean image, the student a degraded view, creating free on-policy supervision. Instead of privileged teachers or labels, it creates asymmetry by weakening the student view. An EMA teacher scores clean images while the student learns on augmented views, turning visual corruption into on-policy distillation signal.

Key results

  • 77.44% avg, up from 70.68% on 6 perception benchmarks
  • Beats Qwen3-VL-Instruct-235B: 77.44% vs 75.75% avg
  • Recovers 96% of the gain from privileged-information methods

Teacher-student asymmetry for on-policy distillation can come from subtracting input information from the student, not adding privileged information to the teacher.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.