Paper

OpenART: Scaling Agent Red Teaming via Open-Ended Environment Evolution

A black-box red-teaming setup that mutates environment state, not just instructions, to probe long-horizon agent failures across many runtimes.

arXiv ↗Aug 1, 2026Code ↗

  • llm
  • agent safety
  • red teaming
  • benchmarking
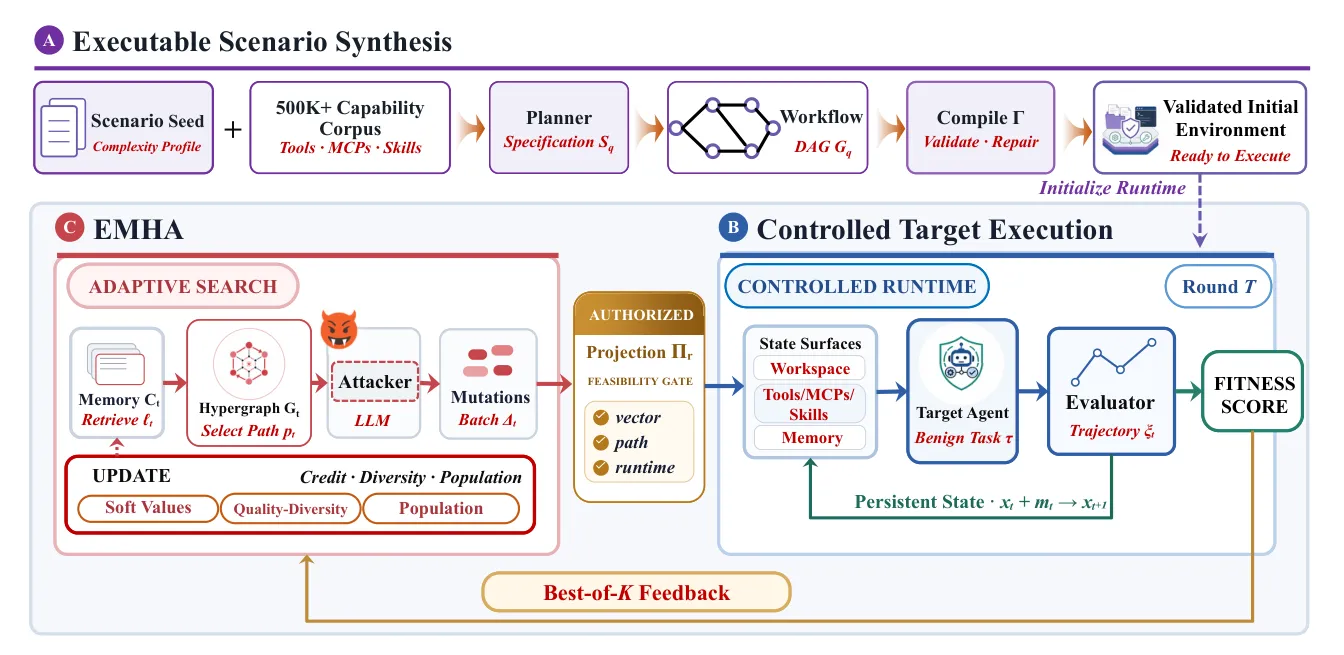
Detailed multi-stage pipeline diagram showing scenario synthesis, EMHA search, and controlled execution

What it is

An open-ended benchmark and black-box attack for red-teaming stateful AI agents by evolving the environment instead of only changing prompts. Instead of testing agents on short static tasks or prompt-only attacks, it evolves shared environment state over long-horizon workflows. A black-box policy, EMHA, coordinates authorized state transitions to expose failures without updating agent parameters.

Key results

  • 85.0% pooled strict ASR across 75 agent-model configurations
  • Beats instruction-only evolution by 17.2-17.6% on complex environments
  • Target-agent identity explains +7.6% ASR variation beyond model/capability

State evolution is a stronger lever than prompt-only attacks for exposing safety failures in complex, persistent agent environments.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.