
What it is
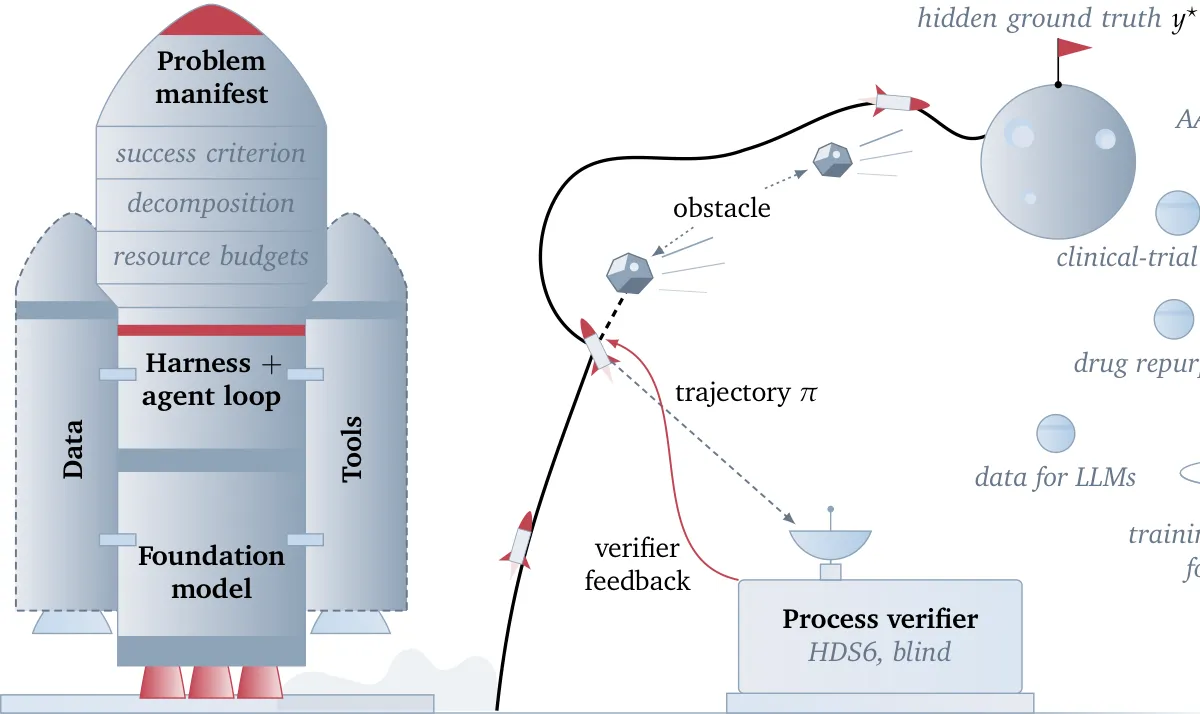
A framework and benchmark for evaluating AI systems on long-horizon, verifiable real-world discovery tasks using executable environments and process scoring. Instead of static QA or narrow interactive benchmarks, it evaluates full solver systems in executable, stateful environments with hidden verifiers, repair loops, and HDS6 process scoring over trajectories.
Key results
- AAV capsid design: 7% above published SOTA across 4 tasks
- Drug tasks: GPT-5.6-sol gains 7.6 normalized points vs closed-book
- Drug tasks: GPT-5.5 gains 2.5 normalized points vs closed-book
Shows that reality-based task environments and process verification expose and improve capabilities needed for sustained discovery work.