Dataset

Q-CARE Benchmark

Contains 800 QA queries from 8 source datasets with inlined top-30 retrieved chunks from 2 retrievers and 16 RAG answers per query.

Hugging Face ↗Aug 26, 2026Code ↗

  • nlp
  • llm
  • rag-evaluation
  • reference-free
  • hallucination
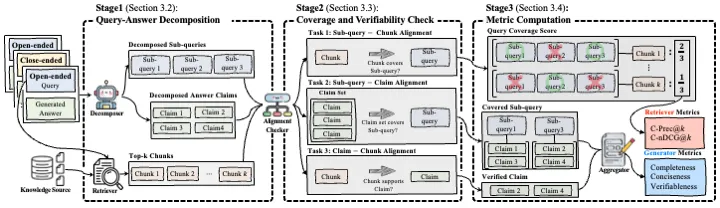
Multi-stage pipeline diagram showing method's decomposition, verification, and metric computation stages

What it is

A compact RAG evaluation benchmark with 800 queries, inlined retrieval, and 16 system answers per query for reference-free scoring across close- and open-ended QA. 800 English queries across 8 QA sources, split into close- and open-ended settings, with top-30 BM25 and ANCE chunks plus 16 answers per query from 8 RAG systems over both retrievers.

Key results

  • 800 queries across 8 source datasets
  • 2 retrievers: BM25 and ANCE, 30 chunks each
  • 12,800 answers from 8 systems under both retrievers

Useful for benchmarking retrieval and answer quality in RAG with the same fixed queries and retrieved evidence.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.