
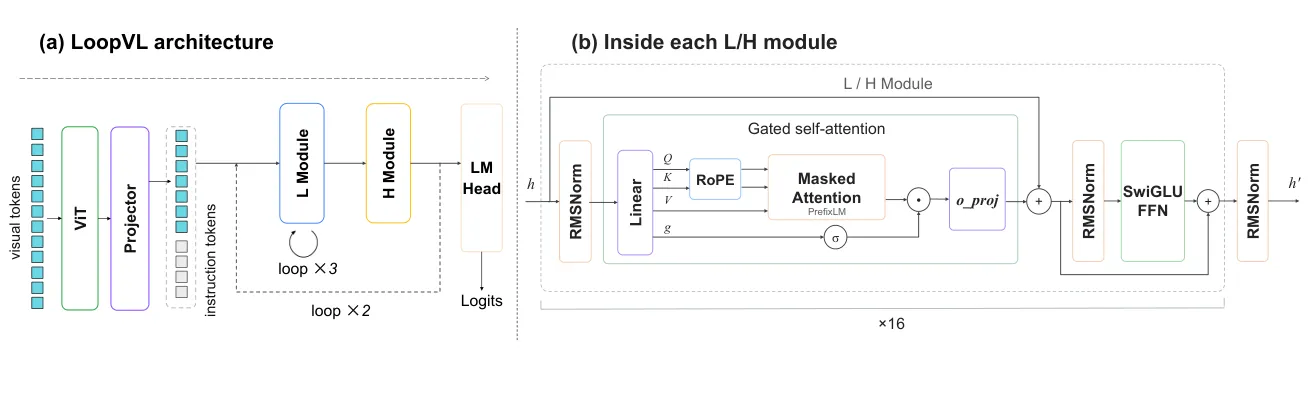
What it is
Vision-language model repo for recurrent visual computation, plus reproducible evaluation and analysis across 16 benchmarks and visual-state experiments. Run a vision-language model that reuses transformer modules across recurrent visual passes, and reproduce its benchmark suite plus attention and hidden-state analyses.
Key results
- LoopVL-1B uses 128 effective layer applications per forward pass
- Evaluates on 16 datasets with resumable runs and 1-4 workers per GPU
- Includes 12 schedule tests across 5 datasets plus Figure 3 control runs
Shows that a single VLM checkpoint can be probed under different recurrent computation schedules and visual-state controls.