Repo

VisionHOPE

Provides self-modifying vision backbones and standalone image/sequence operators, plus training, eval, and fused fast-inference paths in PyTorch.

GitHub ↗Sep 27, 2026Paper ↗

  • cv
  • vision-backbone
  • imagenet
  • dense-prediction
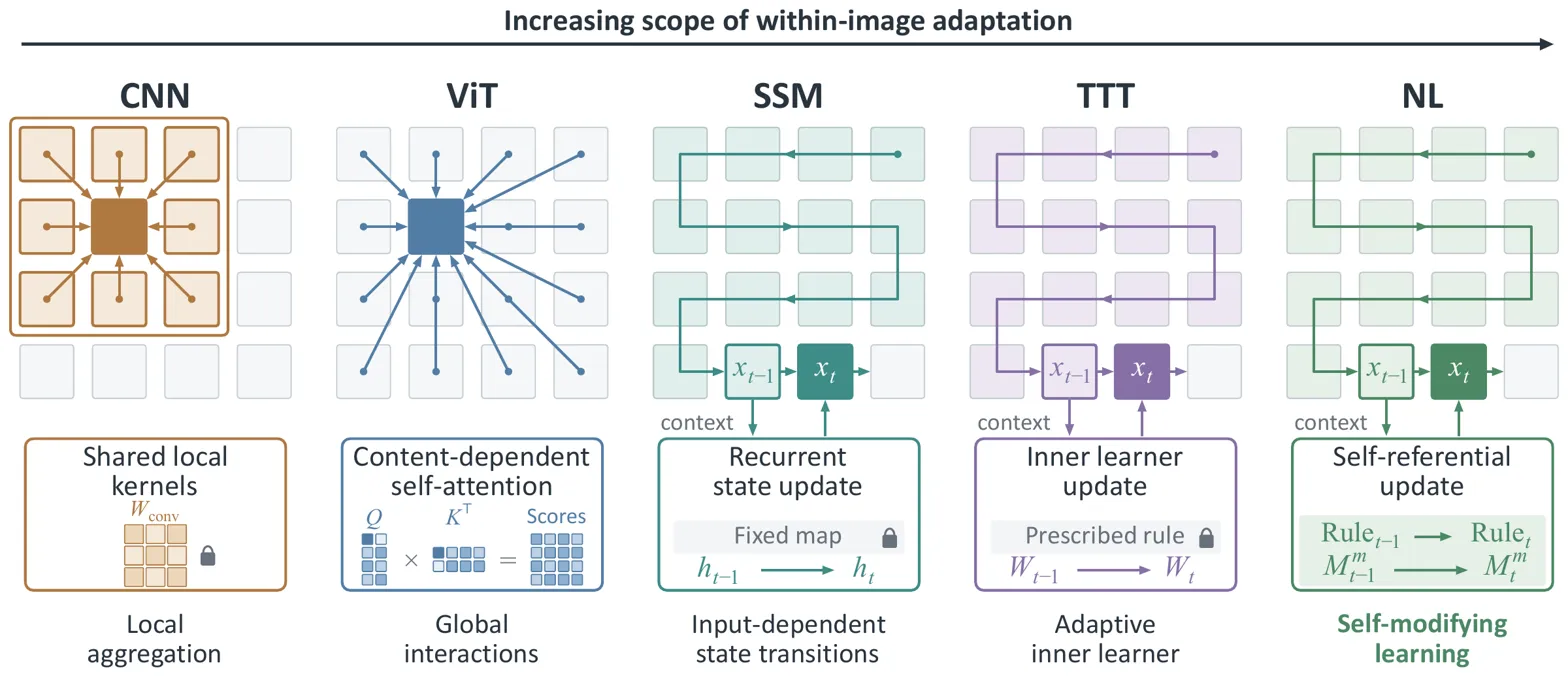
Conceptual diagram comparing architectures across spectrum of within-image adaptation scope

What it is

PyTorch visual backbones built around self-modifying memory updates during image processing, with pretrained models for classification, detection, and segmentation. Use a visual backbone whose internal memories and learning dynamics evolve while scanning an image, with ready-to-run PyTorch models and standalone SRNL/operator modules.

Key results

  • ImageNet-1K: 84.1/85.2/85.6 top-1 for Tiny/Small/Base
  • COCO Mask R-CNN: up to 50.5 box AP and 45.0 mask AP
  • ADE20K UPerNet: up to 51.8 mIoU with released checkpoints

Shows a vision backbone can update coupled memories and learning behavior within a single image pass while remaining usable across classification and dense prediction.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.