
What it is
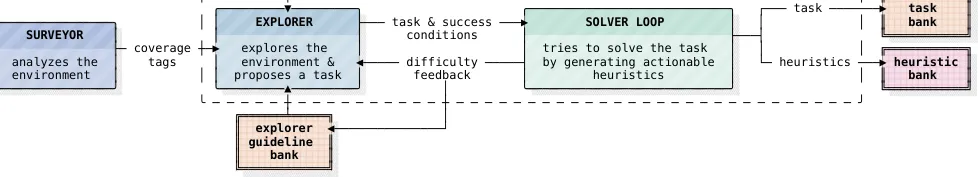
Run artifacts for DAEDALUS agent-memory experiments: generated tasks, self-play sessions, heuristic banks, judge verdicts, and full trajectories across three benchmarks. 10K-100K run artifacts across 3 agent benchmarks: generated tasks, heuristic banks, self-play sessions, explorer/solver transcripts, judge verdicts, and inference trajectories from DAEDALUS and baseline runs.
Key results
- 10K-100K artifacts
- 3 benchmarks: AppWorld, τ²-bench, AutomationBench
- Parquet samples plus full run folders; mixed license
Useful for reproducing and analyzing how self-play-generated memory affects agent task performance.