Dataset

ScholarCatalyst

Contains a 190,896-paper text corpus plus 894 research questions from 207 CS projects, with author-labeled inspiring papers, hard negatives, and rationales.

Hugging Face ↗Oct 1, 2026Paper ↗Code ↗

  • nlp
  • text-retrieval
  • literature-retrieval
  • scientific-discovery
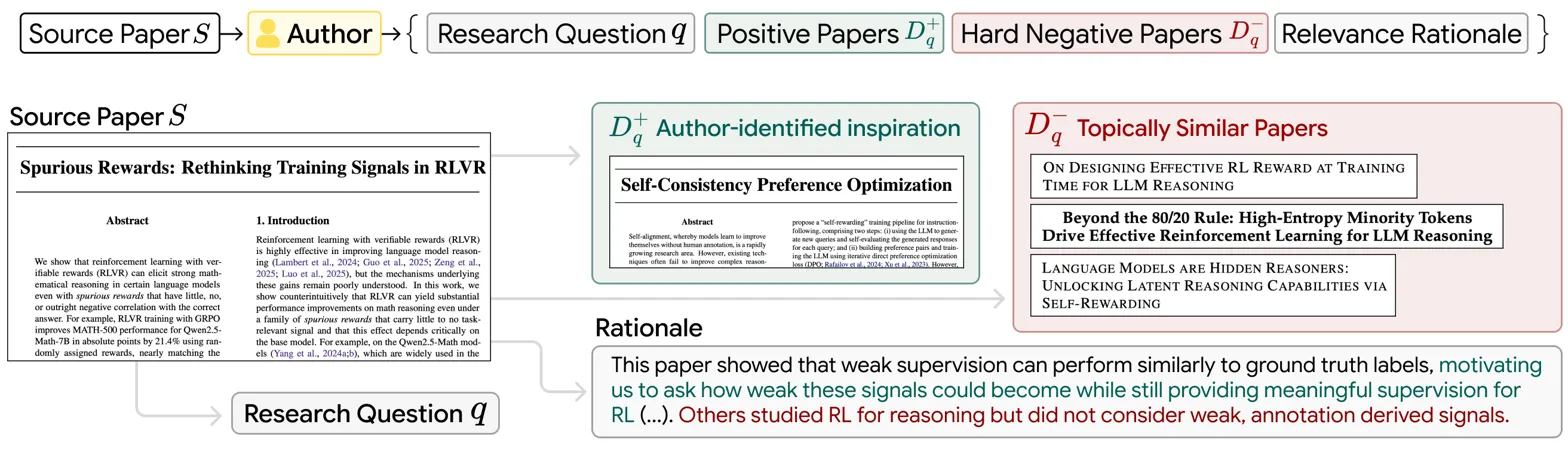
Pipeline diagram showing dataset construction with annotated examples of each component

What it is

Benchmark for retrieving prior papers that genuinely inspired new research, using author-verified questions, positives, hard negatives, and rationales. 191k-paper corpus with 894 author-verified research questions from 207 CS projects, plus relevance labels, hard negatives, and rationale annotations for core-paper and subfield retrieval.

Key results

  • 190,896 paper title+abstract documents
  • 894 queries from 207 projects by 184 researchers
  • CC-BY-NC-4.0; 207 core and 687 subfield query judgments

Useful for evaluating retrieval systems that find papers likely to inspire a new research project or idea thread.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.