
What it is
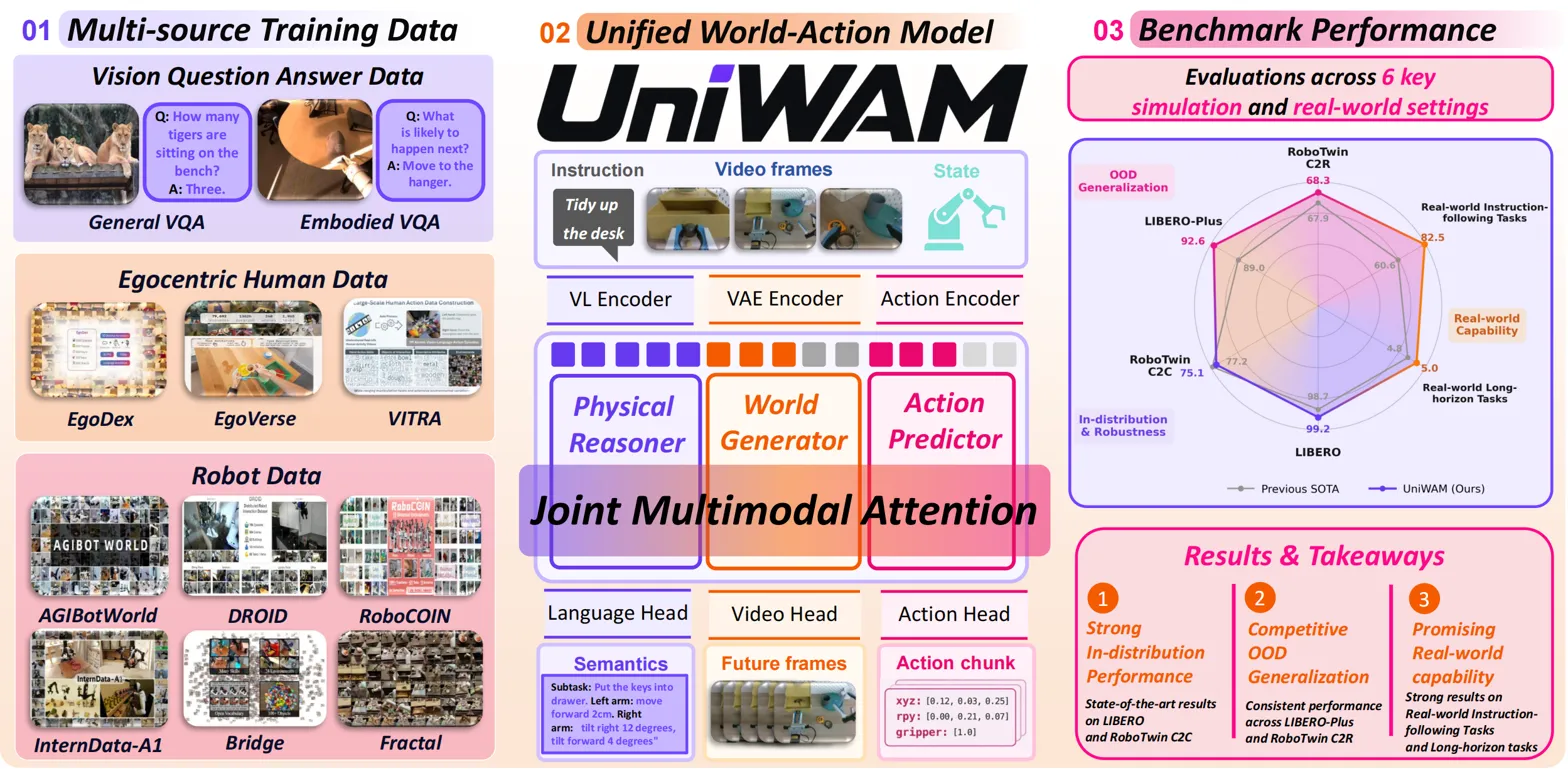
UniWAM unifies a VLM reasoner, video world model, and action predictor for robot control. It co-trains on VQA, human egocentric, and robot data to improve reasoning, dynamics, and action generation. Instead of choosing VLA semantics or WAM dynamics, it trains both in one model: a VLM reasoner, world generator, and action predictor with component-specific supervision. Low-level actions are expressed in natural language, and post-training ties noisy future visuals plus action history into fast flow-based action generation.
Key results
- SOTA on LIBERO and RoboTwin C2C in in-distribution evaluation
- Consistent OOD performance across LIBERO-Plus and RoboTwin C2R
- Strong real-world instruction-following and long-horizon task results
Combining semantic supervision from VLM pretraining with world-model dynamics in one policy improves robustness and generalization for embodied control.