
What it is
A real-time robot world-action model that scales to long visual histories by using autoregressive video pretraining and causal action adaptation, plus systems optimizations for edge deployment. Instead of adapting bidirectionally pretrained video models, it pretrains video autoregressively on robot/egocentric data and keeps that causal history-to-future structure during action adaptation, so longer visual context actually improves control.
Key results
- RoboCasa GR-1: 78.7% at 19.2s history vs 63.3% with no history
- LIBERO-Long: 99.5% with 2.4s history vs 94.5% with no history
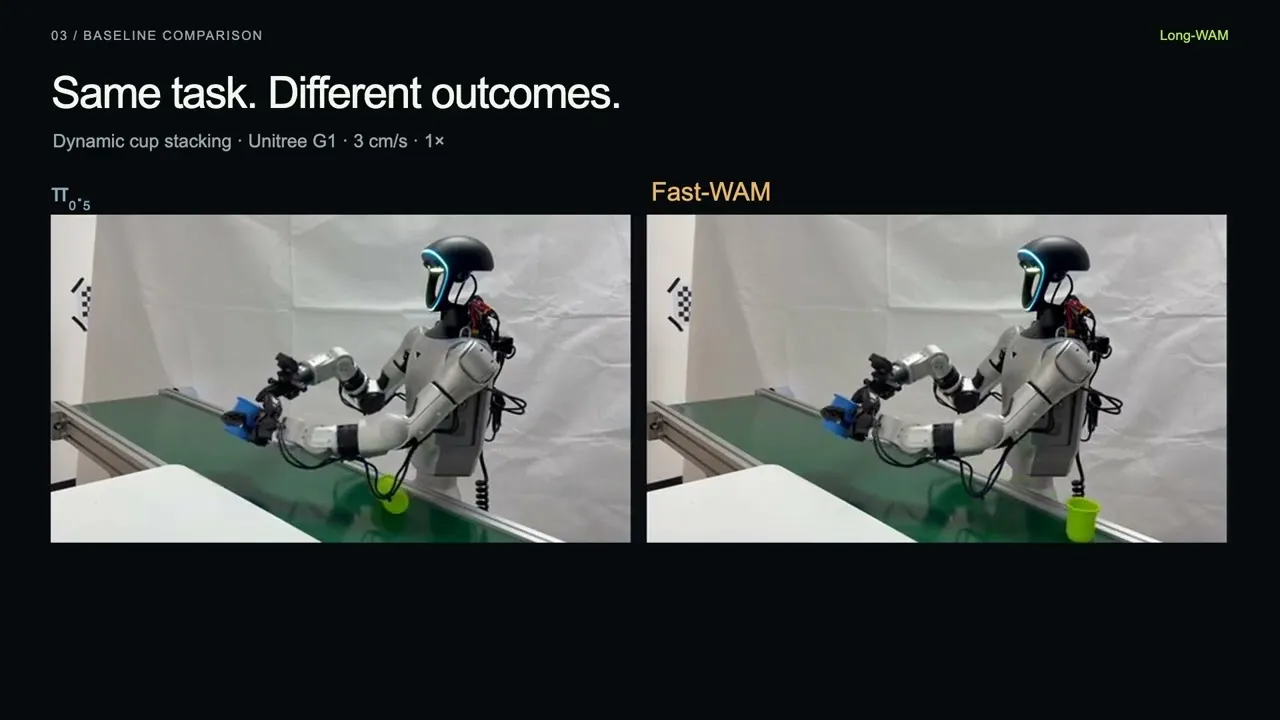
- Dynamic cup stacking: 95% on G1; pi0.5 and Fast-WAM got 0/20
Long context helps robot control only when the foundation model is pretrained to predict causally from history, not just given more memory.