
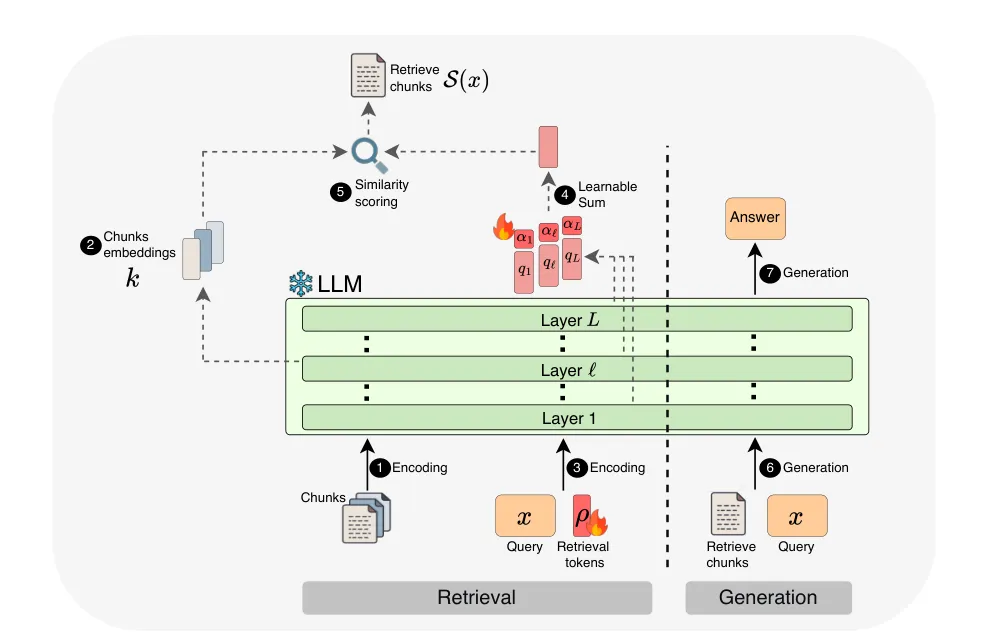
What it is
A frozen LLM is turned into both a corpus retriever and long-context selector using its own internal states, with under 500K trained params. Instead of using an external retriever or full-context reading, it ranks evidence from the frozen LLM's residual states. The same tiny module handles corpus retrieval and long-context chunk selection across decoder-only and hybrid backbones.
Key results
- HotpotQA recall@10: 73.2% vs 49.1% for best retriever-reranker baseline
- 2Wiki recall@10: 60.1% vs 31.7% baseline on 21M Wikipedia chunks
- NoLiMa at 128K: 24.83% accuracy vs 1.0% with full-context inference
Shows one small internal retrieval head can unify corpus-scale RAG and sparse-evidence long-context inference without backbone finetuning.