Repo

MOSS-Image

Generates images from prompts or layout JSON, with controllable text/object placement and readable embedded text. Ships Diffusers, Gradio, and ComfyUI support.

GitHub ↗Oct 16, 2026Paper ↗

  • multimodal
  • text-to-image
  • layout-control
  • text-rendering
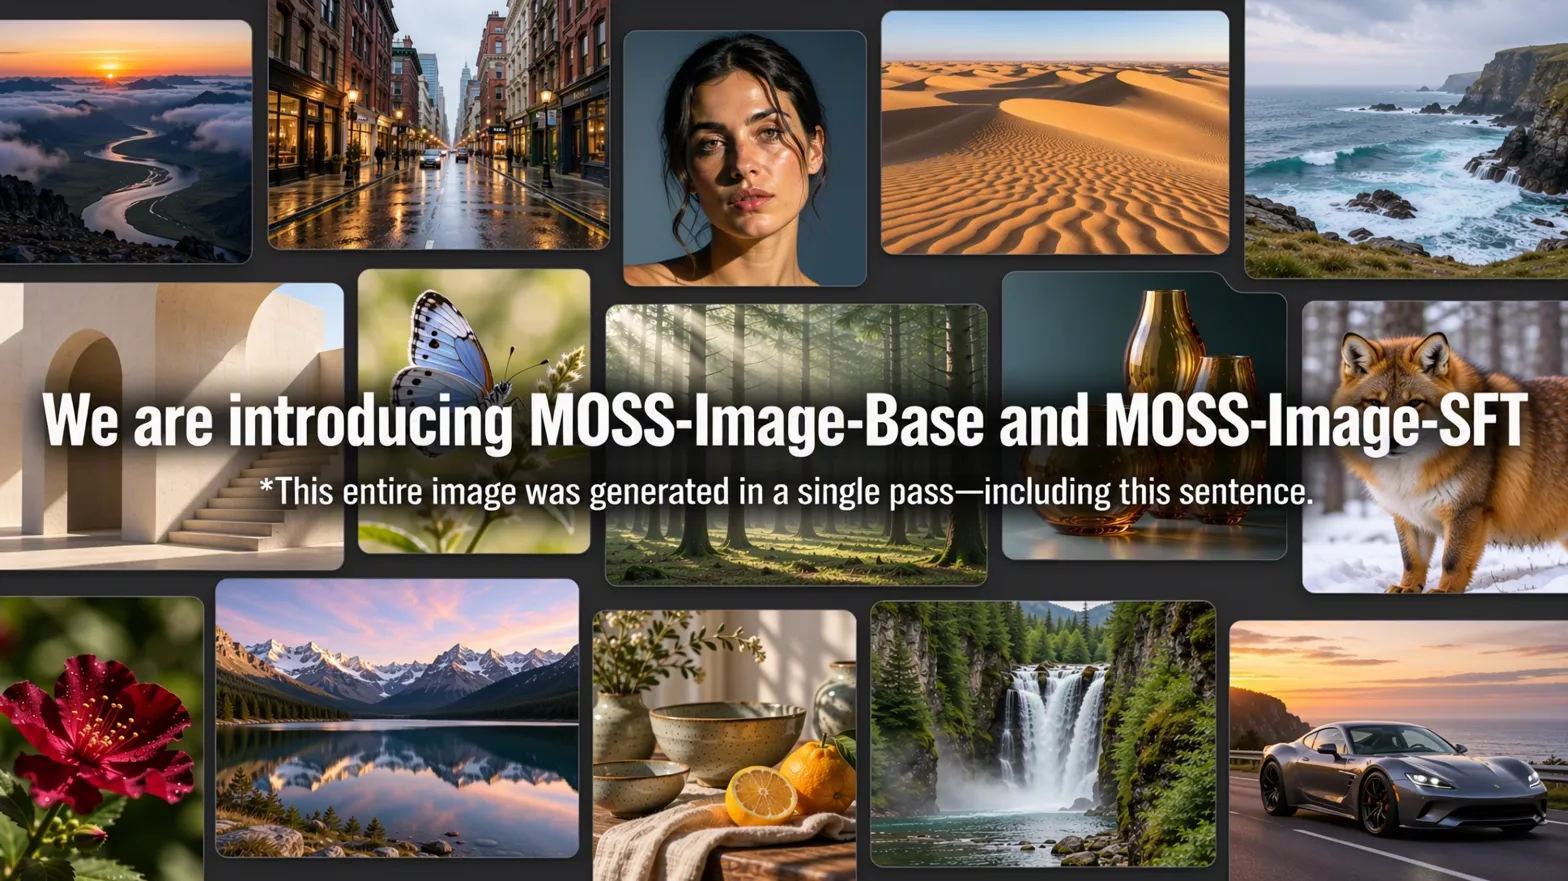
Composite showcasing varied generated images plus text, demonstrating the model's single-pass output capability

What it is

Open 5B text-to-image DiT with strong text rendering, JSON layout control, and 4K-token prompts, plus public weights and fine-tuning support. Generate images with explicit text placement and object layout, long prompts, and readable in-image text using a public 5B text-to-image model with base and SFT checkpoints.

Key results

  • Supports prompts up to 4K tokens
  • Provides JSON layout control with bbox-based element placement
  • Releases public 5B base and SFT checkpoints with LoRA guidance

Shows that a public 5B image model can combine long-prompt support, layout control, and strong text rendering in one stack.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.