Paper

Learning to Think and Explore in 3D World

A single-view interactive VLM that learns to navigate for evidence instead of consuming full 3D or video inputs. It is SFT-initialized, then RL-trained from answer outcomes.

arXiv ↗Oct 15, 2026

  • cv
  • multimodal
  • 3d reasoning
  • visual question answering
  • reinforcement learning
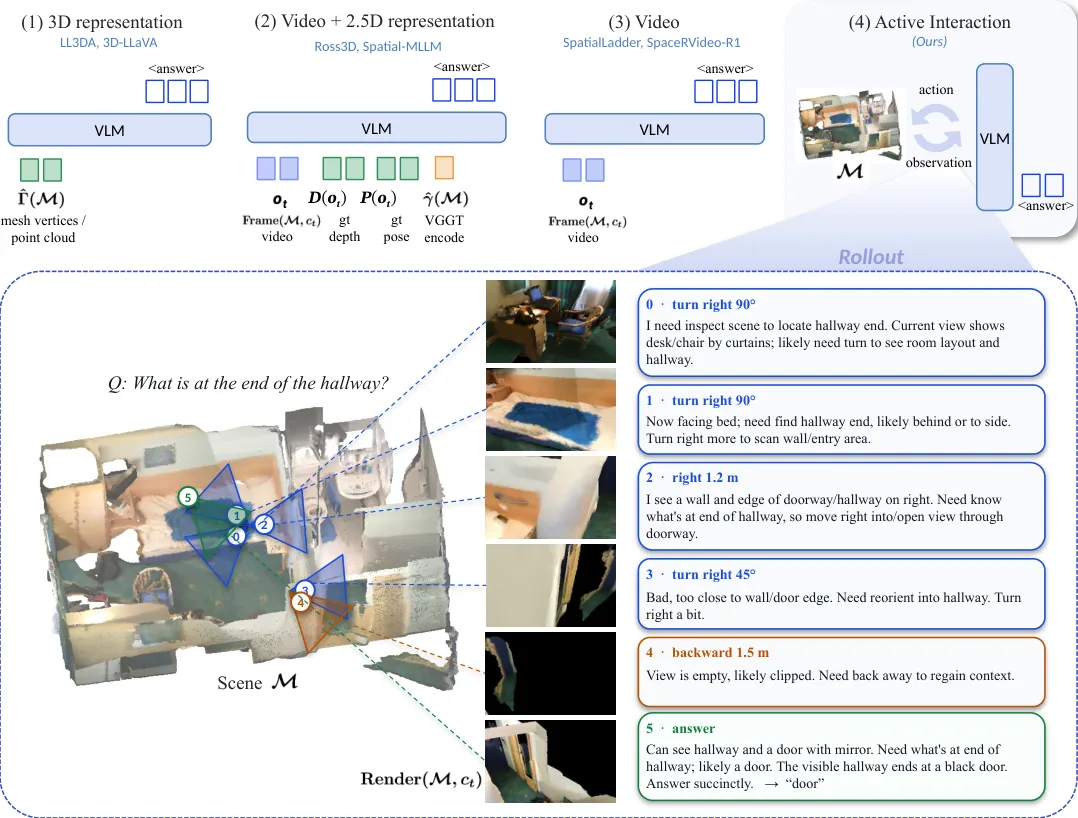
Compares paradigms and shows active interaction pipeline with rollout example illustrating core contribution

What it is

A VLM learns to answer 3D questions by actively moving through a scene one view at a time, then answering after RL-trained exploration and reasoning. Instead of feeding full 3D, video, or multiview inputs, it keeps the 3D scene external and trains a single-image VLM to explore via actions. RL uses mainly final answer correctness, with no trajectory labels for where to look.

Key results

  • 53.2% avg accuracy on 6 benchmarks, +22.0% over base Qwen
  • Beats Gemini 3.6 Flash by 1.0% average accuracy
  • Uses 50-70% fewer input frames than prior open-source 3D methods

Outcome-based RL can teach VLMs not just to reason from observations, but to acquire the right observations for 3D tasks.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.