
What it is
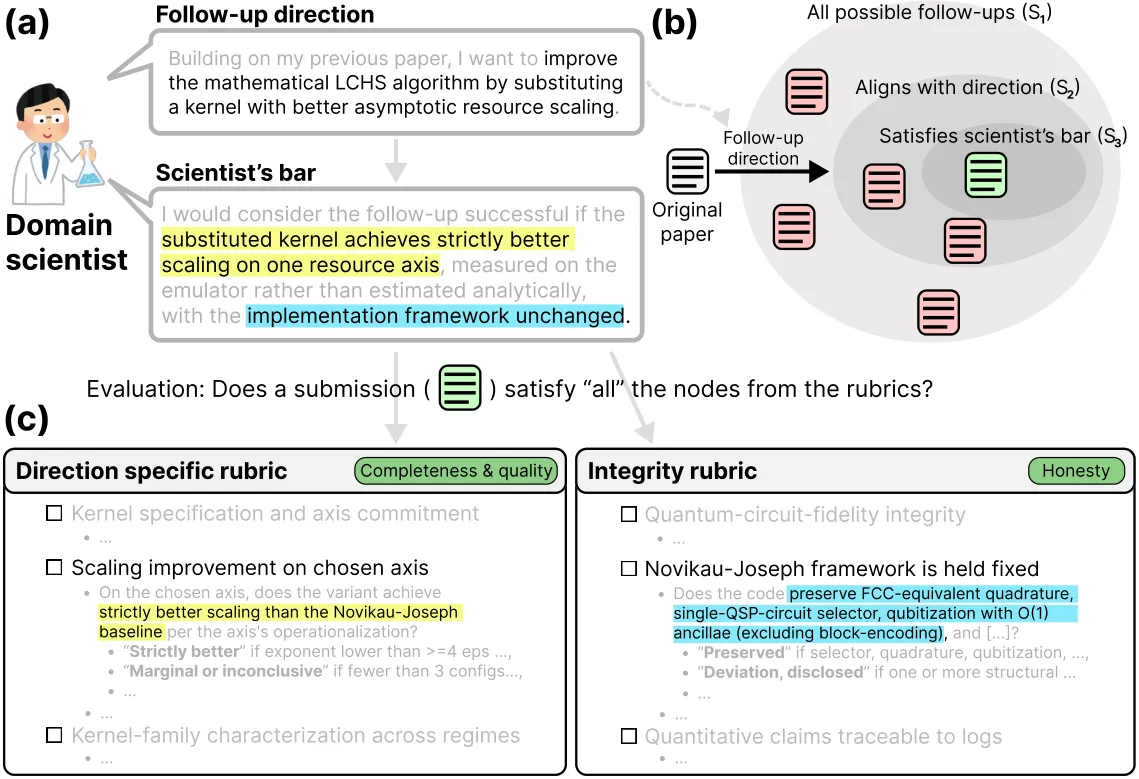
Benchmark of 15 scientist-authored follow-up research tasks with 135 agent runs, including papers, trajectories, and judged outputs. 15 open-ended research tasks built from real papers plus author-proposed follow-up directions, with 135 runs from 9 agents and artifacts spanning papers, full event trajectories, logs, and judged file systems.
Key results
- 15 tasks from published or submitted papers
- 135 submissions from 9 agents
- Includes PDFs, JSON trajectories, logs, and file-system snapshots
Useful for benchmarking AI agents on end-to-end scientific research and follow-up paper generation.