Paper

EgoXperience: Learning World-Grounded Egocentric Representations from Human Experience

A joint feed-forward model for egocentric video that predicts camera, depth, hands, and object poses together in one metric world frame.

arXiv ↗Oct 19, 2026Code ↗

  • cv
  • egocentric vision
  • 3d reconstruction
  • hand-object interaction
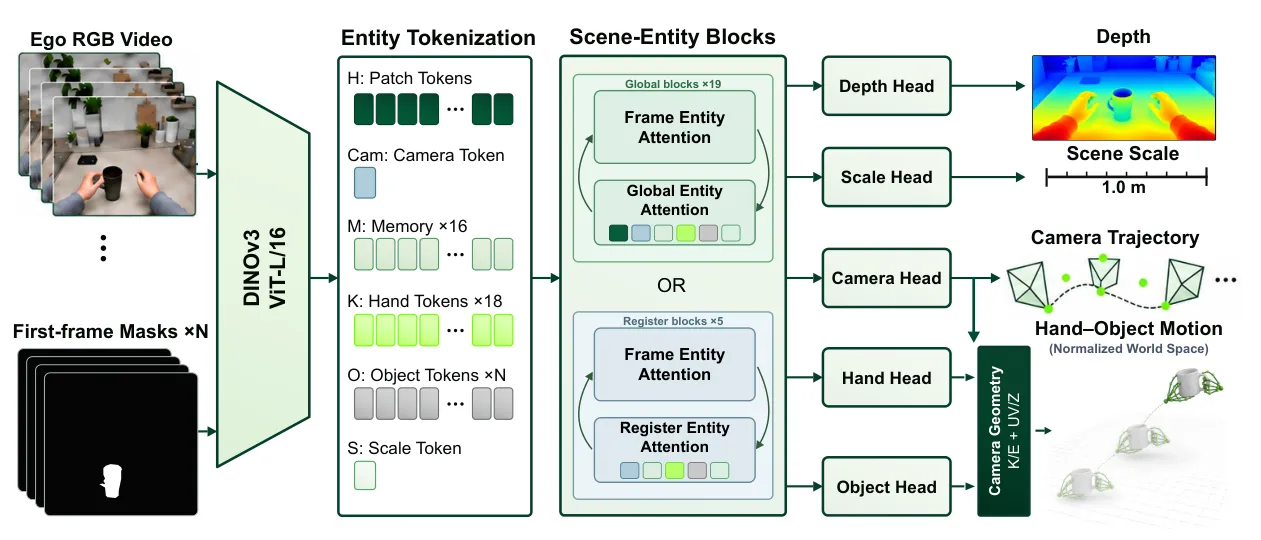
Full pipeline diagram showing tokenization, scene-entity blocks, and output heads

What it is

A full-stack egocentric 3D reconstruction setup: dataset, auto-annotation engine, benchmark, and a feed-forward model that jointly predicts camera, depth, hands, and objects in one world frame. Instead of stitching separate camera, depth, hand, and object systems, it learns them jointly in a shared metric world frame. It pairs SLAM-aligned auto-annotations with a single-pass model whose world-space supervision explicitly couples camera and hand-object predictions.

Key results

  • HOI4D camera nATE reduced by 68.9% vs strongest baseline
  • EgoX-Bench hand W-MPJPE and depth AbsRel cut by 65.6% and 42.9%
  • HOT3D object AUC-S50 improves by 28.0% vs strongest baseline

Joint world-space supervision across camera, scene, hands, and objects yields much more coherent egocentric reconstruction than separate pipelines.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.