
What it is
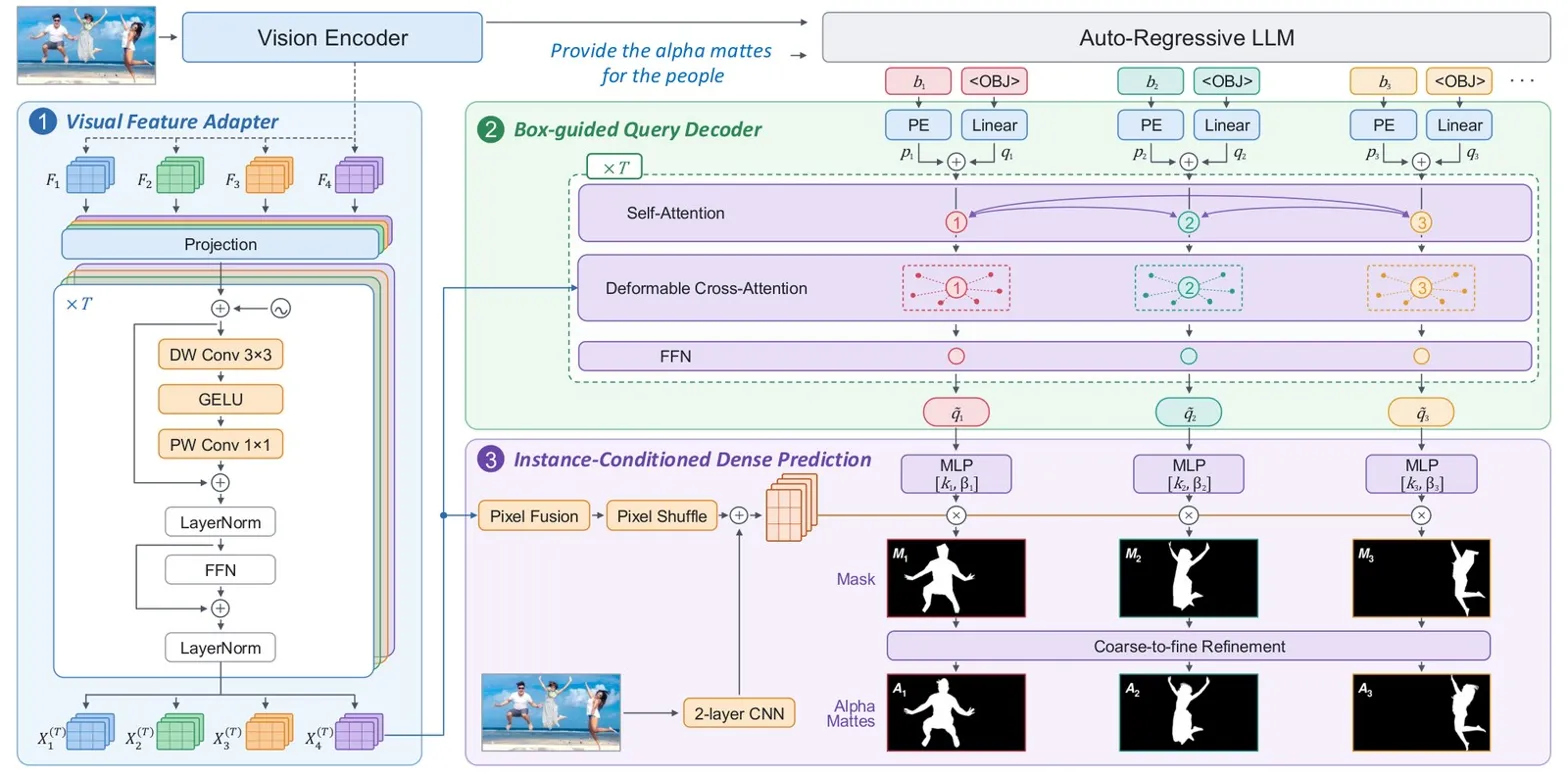
Vision-language model for unified object- and pixel-level perception, covering boxes, points, masks, and alpha mattes in one system. Handle detection, referring, counting, pointing, OCR, segmentation, and alpha matting in one VLM, returning outputs from points and boxes to masks and mattes, including None for absent targets.
Key results
- One model covers detection, OCR, segmentation, and matting
- Uses a 9.6M decoder for masks and alpha mattes; no SAM required
- Returns None for absent targets; 96.4% rejection on WeRef-Bench
Shows a single VLM can unify open-vocabulary localization and high-quality pixel outputs, including alpha matting, without a separate SAM stage.