
What it is
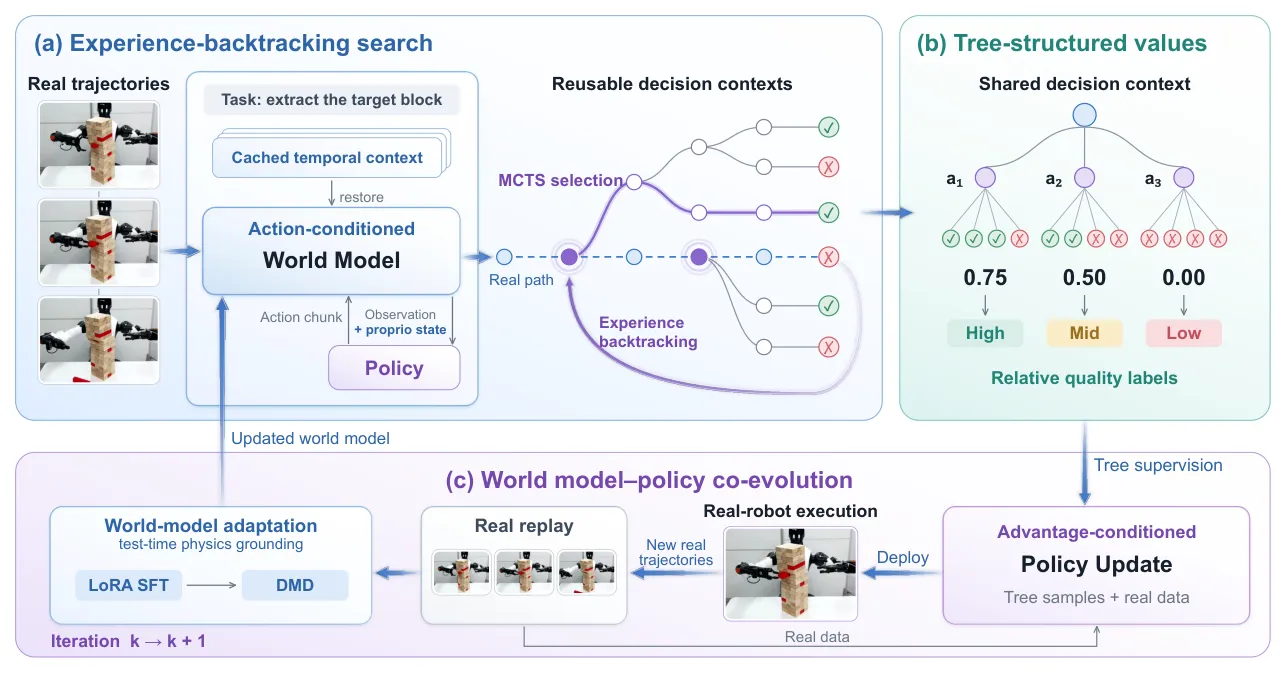
Uses rewindable world models to backtrack to key robot decisions, branch counterfactual actions, and train policies from action-level comparisons plus real-world grounding. Instead of only doing forward imagined rollouts, it rewinds world-model states to critical decisions, branches alternative actions, and learns from sibling outcome differences. MCTS focuses compute on informative branches, and real robot data continually re-grounds the simulator.
Key results
- +11.85% success over strongest baseline on tabletop curling
- +11.11% success over strongest baseline on ball tossing
- +10.67% success over strongest baseline on block extraction
World models become much more useful for robot policy learning when used as rewindable counterfactual search environments and continually corrected with real experience.