
What it is
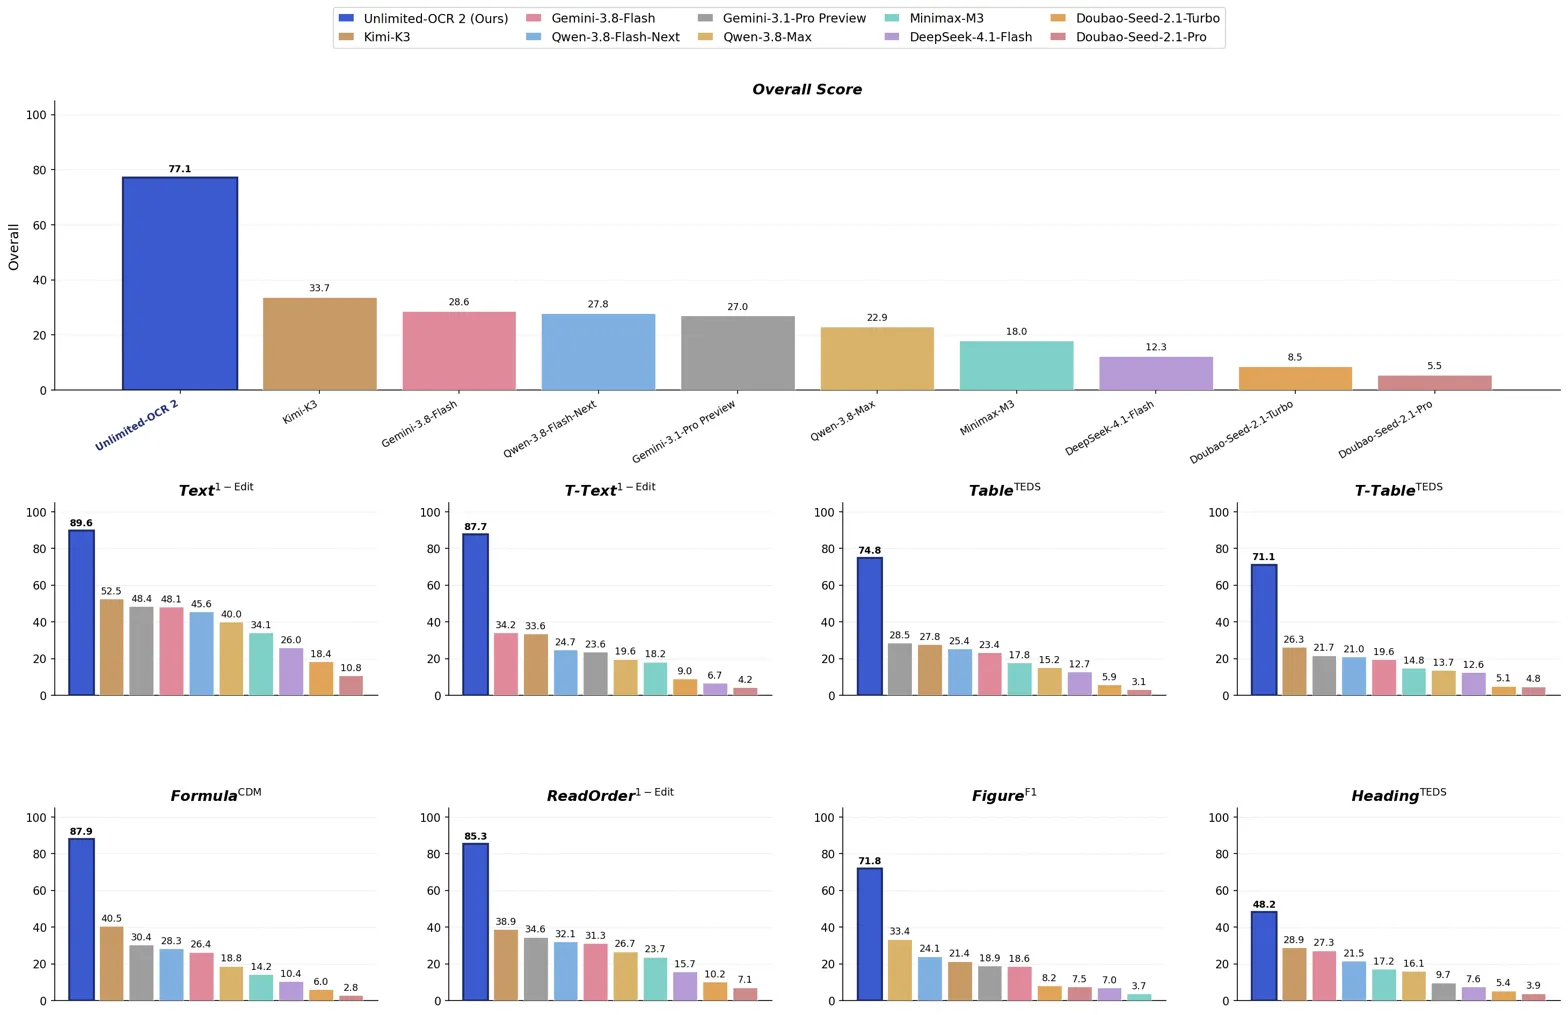
Benchmark for parsing hundred-page documents with page images and dense cross-page annotations. It targets ultra-long OCR/layout extraction where page-wise parsers break. 100 documents of 100-300 pages each (~18k pages, ~205k layout elements), with page images plus bilingual annotations for boxes, types, hierarchy, reading order, and cross-page text/table continuations.
Key results
- 100 documents spanning 100-300 pages each
- ~18k PNG pages and ~205k annotated layout elements
- Annotations include boxes, order, hierarchy, and cross-page merges
Useful for benchmarking OCR and layout parsers on hundred-page documents with cross-page text and tables.