
What it is
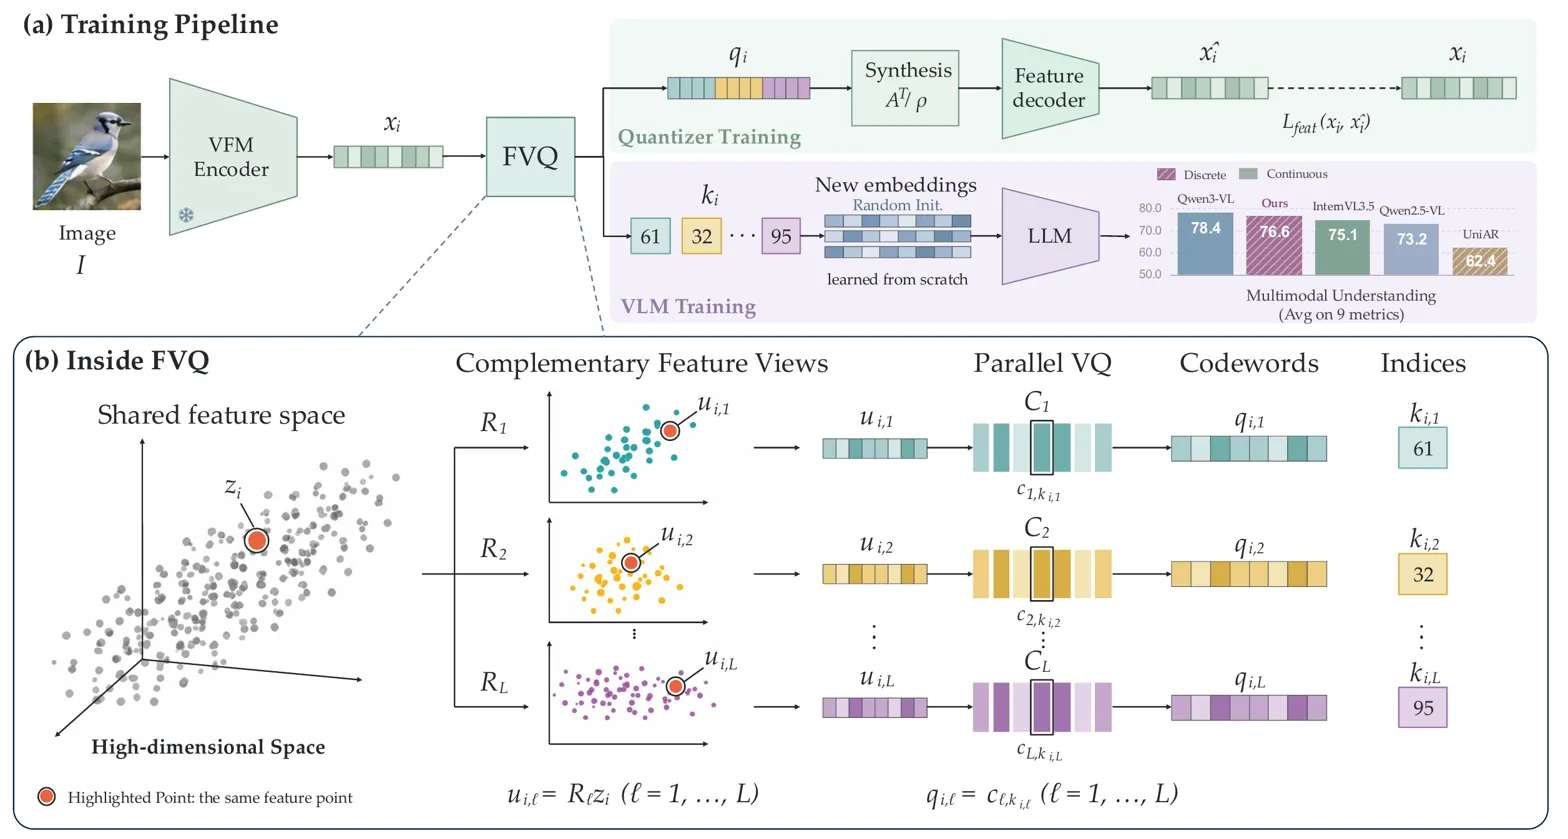
Tests whether discrete visual tokens can be semantically lossless and introduces FVQ, a quantizer that scales bit budget without saturating, matching continuous vision features. Instead of treating quantization error as the limit, it scales semantic capacity via bit budget. FVQ replaces residual or split-channel codebooks with symmetric parallel codebooks over complementary full-feature views, avoiding high-budget saturation.
Key results
- 65.3 avg on 8 benchmarks vs 64.6 for continuous QwenViT
- 22.8% higher 9-metric average than UniAR
- 59.2% higher 9-metric average than Emu3-Chat
Discrete visual tokens can match continuous visual representations when added bits remain semantically informative.