Repo

detectorscope

Explains AI-text predictions with named feature contributions and token highlights by gating detector decisions through validated interpretable features.

GitHub ↗Oct 24, 2026Paper ↗

  • nlp
  • ai-text-detection
  • mechanistic-interpretability
  • sparse-autoencoders
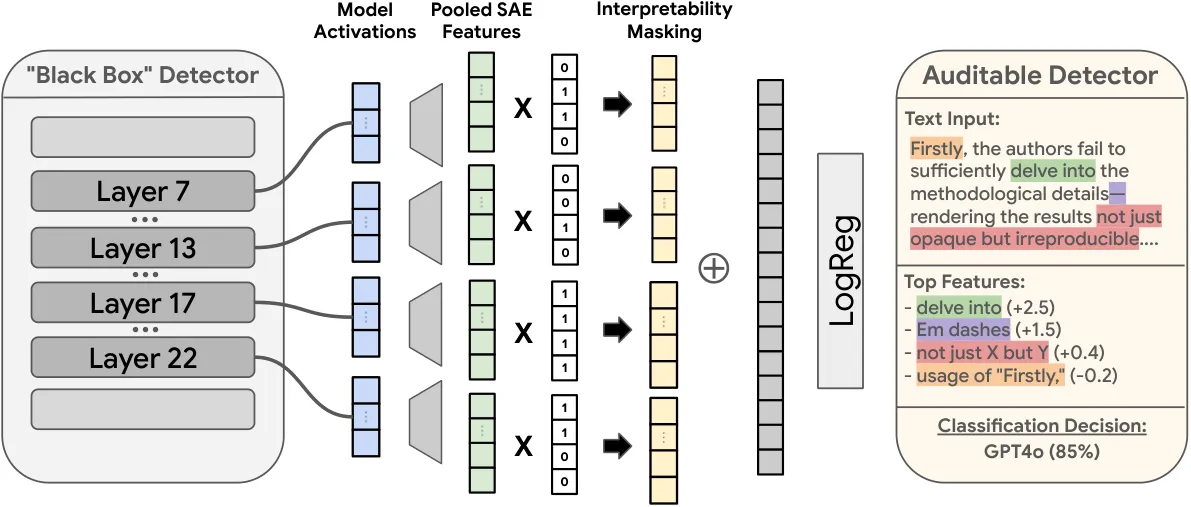
Pipeline diagram showing SAE feature extraction and auditable detector method

What it is

Builds AI text detectors that explain each prediction as a sum of named, validated features with token-level evidence, while staying close to the original detector's accuracy. Turn a black-box AI text detector into an auditable one that reports named feature contributions and token-level highlights, and provides a pipeline to convert your own detector the same way.

Key results

  • Prediction decomposes exactly: logit = bias + sum(importances)
  • Localizes evidence per feature as token-level highlights
  • Interpretability is tunable with tau from 0.00 to 0.95 without redownloads

Shows AI text detectors can be made human-auditable with explicit feature evidence while retaining near-black-box accuracy.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.