Paper

Hy-Nomas: Towards Free-form Interactive World Generation

A causal video world model that keeps descriptive history accessible but limits action instructions to their intended time windows across turns.

arXiv ↗Oct 27, 2026Code ↗

  • cv
  • video generation
  • world models
  • diffusion models
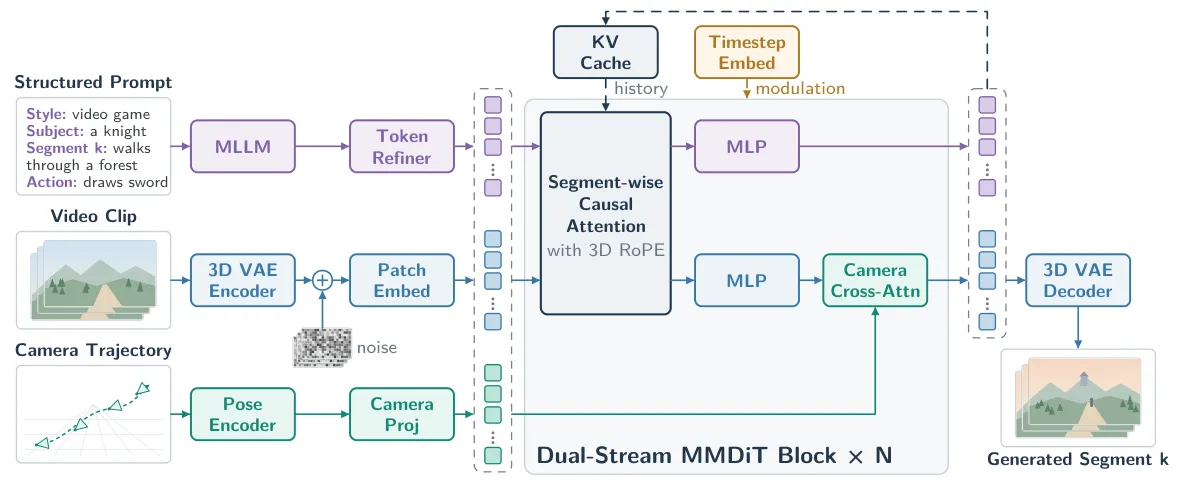
Detailed pipeline diagram showing model architecture with inputs, MMDiT blocks, and outputs

What it is

An 8B diffusion world model for multi-turn video generation that follows free-form text and camera controls while carrying forward scene history across segments. Instead of treating all past prompts equally, it separates persistent scene context from time-local action commands via action-aware causal attention, then uses a VLM prompt planner to turn multimodal history plus user input into the next segment condition.

Key results

  • Beats existing world models in human evaluation on interactive tasks
  • Supports minute-scale rollouts with multi-turn text and camera control
  • Uses an 8B diffusion backbone with packed sequences up to 360K tokens

Structured captions plus temporally scoped action conditioning are key to preserving world state while still obeying new interactive commands.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.