Dataset

BabelArena

Contains parallel multilingual agent tasks across 4 benchmark families, with localized prompts, tools, and environments for agent evaluation.

Hugging Face ↗Oct 22, 2026Paper ↗Code ↗

  • llm
  • agents
  • tool-use
  • multilingual-benchmark
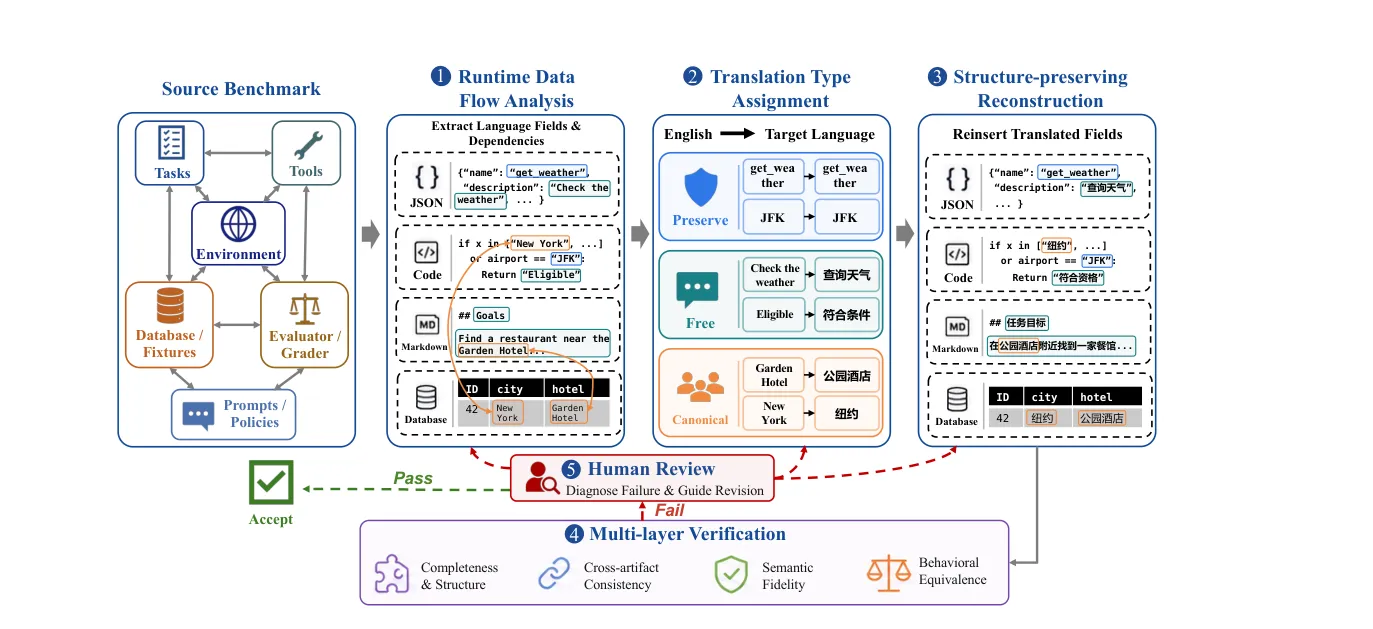
Pipeline diagram showing translation workflow with stages, verification, and human review

What it is

Multilingual benchmark for LLM agents with fully localized tasks, tools, and environments across 23 languages and 13 domains. 16,146 agent task instances from 702 canonical tasks across 4 benchmark families, 23 languages, and 13 domains, with prompts, tasks, tool descriptions, and environments all localized.

Key results

  • 16,146 task instances from 702 canonical tasks
  • 23 languages across 15 scripts and 13 domains
  • Apache-2.0; standard release is 5.2 GiB

Useful for benchmarking multilingual tool-using agents on the same tasks across languages.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.