Repo

OpenWAM

Train and deploy generalist robot policies from modular world-action model components, then evaluate them across supported benchmarks via a WebSocket serving interface.

GitHub ↗Sep 6, 2026Paper ↗

  • robotics
  • world-action-model
  • policy-pretraining
  • benchmark-evaluation
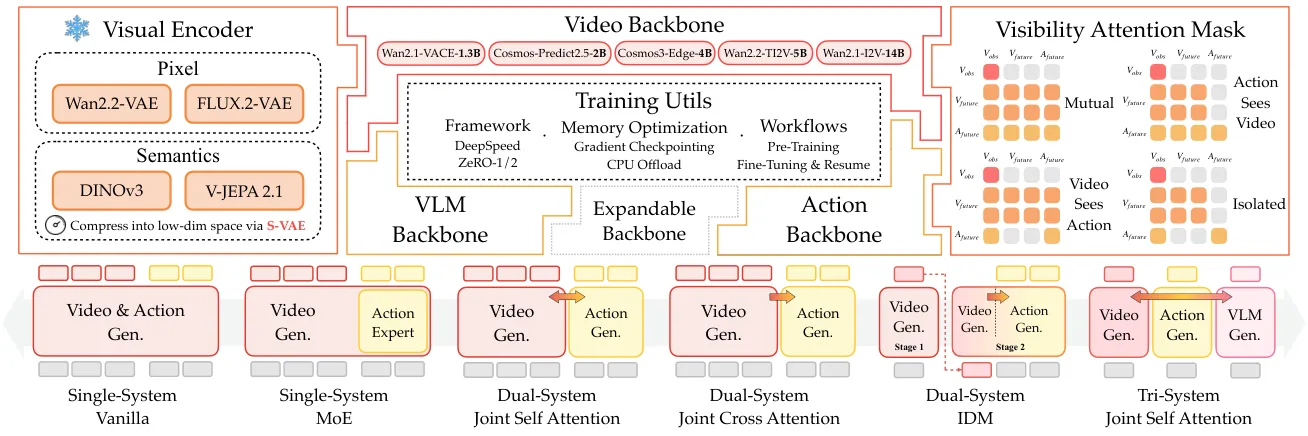
Comprehensive architecture diagram showing components, backbones, attention masks, and system variants

What it is

Modular research stack for training, fine-tuning, and evaluating world-action models, with an open pretrained model trained on 518.5M frames. Build, fine-tune, deploy, and compare world-action models with modular configs for architectures, backbones, datasets, and benchmarks, plus released pretrained checkpoints and benchmark adapters.

Key results

  • OpenWAM-α is pretrained on 518.5M frames, about 6,400 hours
  • Supports RoboTwin, LIBERO, LIBERO-plus, RoboCasa365, VLABench, EBench
  • Released checkpoints are self-contained and deploy directly with scripts/deploy.sh

Shows that world-action model pretraining can be opened up as a modular, benchmarked stack rather than a tightly coupled one-off system.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.