
What it is
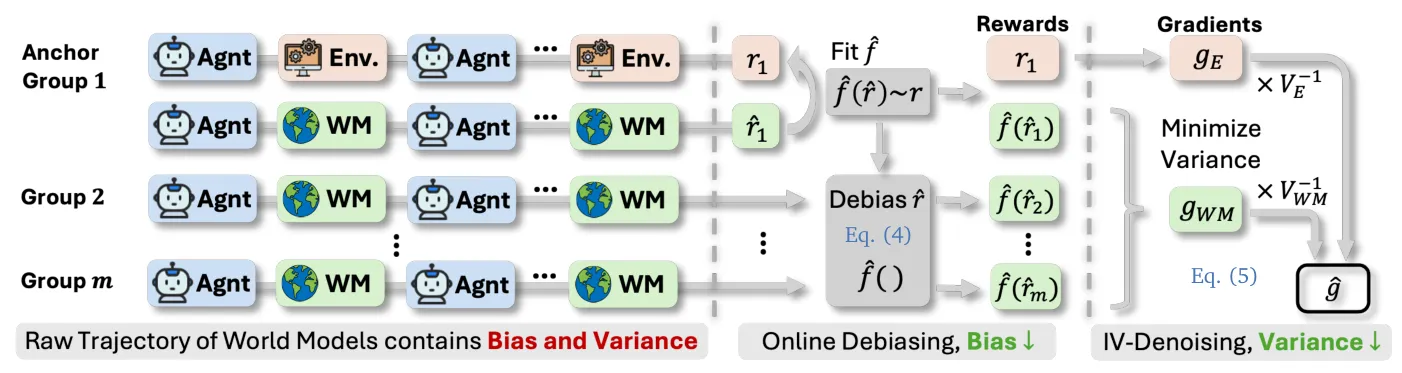
Replaces costly environment execution in RL for automatic research agents with a learned world model, plus online bias and noise correction to keep performance. Instead of paying real execution cost for every RL trajectory, rewards come from a batched world model; a small anchor stream of real executions recalibrates bias and downweights noisy proxy rewards.
Key results
- 3-4x faster training than standard RL on multiple tasks and agent scales
- Post-trained 4B and 9B agents beat larger 48B and 120B open agents
- Transfers to embodied VLA post-training on LIBERO-Long
Shows that a learned reward proxy, anchored by a small amount of real execution, can remove the main RL scaling bottleneck without sacrificing final agent quality.