Dataset

WearableQA

Contains 4,084 multiple-choice questions over real wearable histories, blood biomarkers, and demographics for health and data reasoning tasks.

Hugging Face ↗Sep 3, 2026Paper ↗Code ↗

  • nlp
  • time_series
  • wearable
  • health-qa
  • multiple-choice
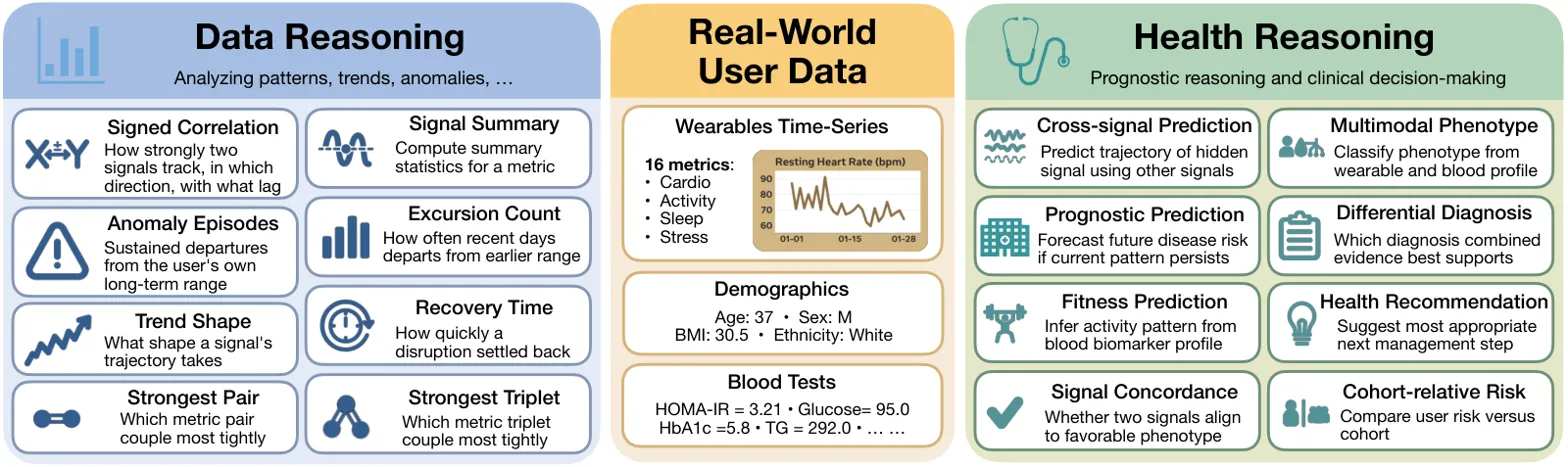
Taxonomy of task categories characterizing dataset's reasoning capabilities and data composition

What it is

Benchmark of 4,084 ten-choice health QA items grounded in real wearable histories, biomarkers, and demographics from 200 users. 4,084 ten-option QA examples from 200 real users, each with up to ~500 days of daily wearable data plus biomarkers and demographics, released in 5 text/structured serializations and 16 question types.

Key results

  • 4,084 ten-option questions
  • 200 real users with up to ~500 daily measurements each
  • 5 representations; 16 question types; CC BY-NC 4.0

Useful for benchmarking QA and reasoning models on real-world wearable health time series.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.