
What it is
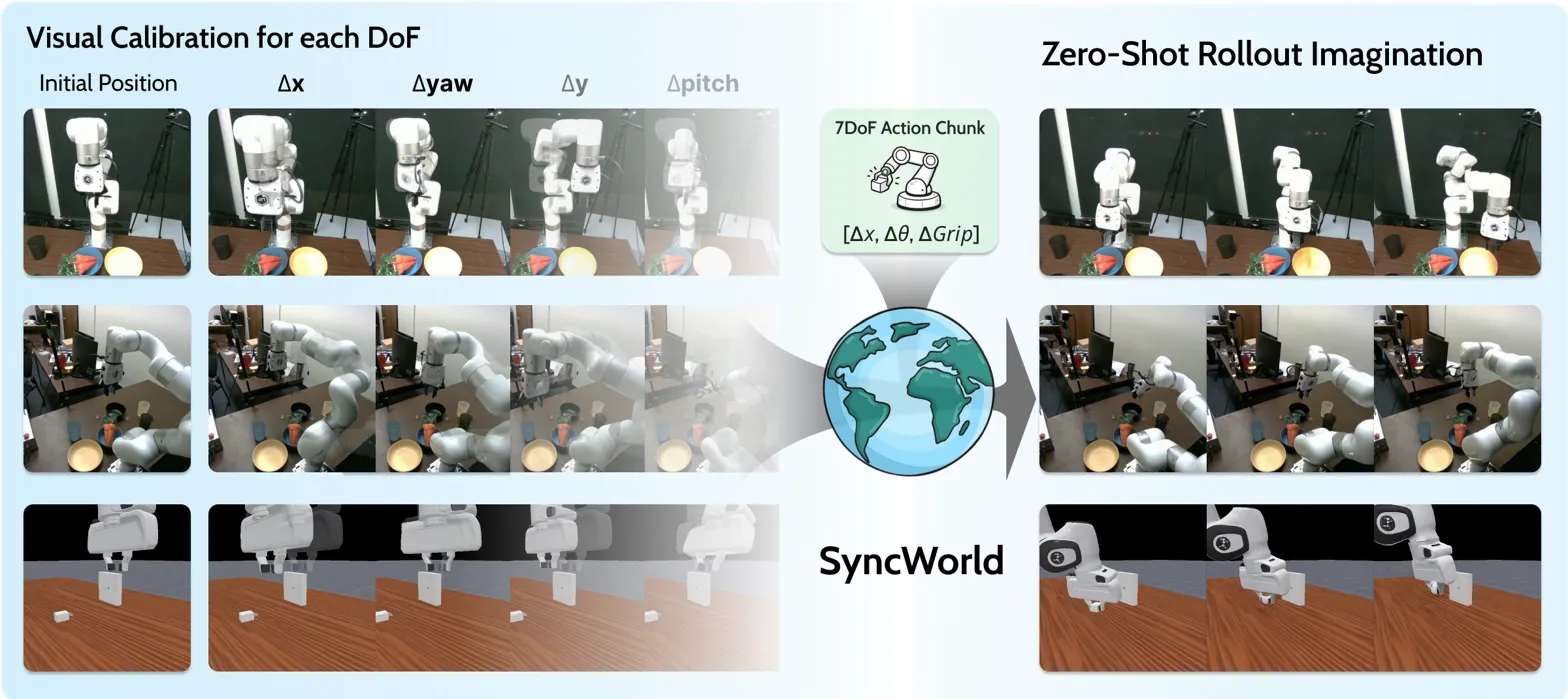
Turns a pretrained video world model into a zero-shot simulator by conditioning on a short visual calibration episode instead of per-setup fine-tuning. Use a short calibration rollout of frames paired with actions to adapt one world-model checkpoint to a new robot setup at inference time and predict future video under actions.
Key results
- Uses paired frames and actions as an inference-time calibration prompt
- Evaluates full-episode rollouts with PSNR, SSIM, and LPIPS
- Released code, weights, and 2 eval sets with 50 episodes each
Shows that action-conditioned world models can be adapted to unseen embodiments and camera setups through visual in-context calibration.