Paper

AuK Technical Report: An Open-Source Foundational Model for Speech Generation and Editing

A unified instruction-following speech model that maps text and optional audio context to generated or edited speech with one flow-based backbone.

arXiv ↗Sep 8, 2026Code ↗

  • audio
  • nlp
  • multimodal
  • speech generation
  • speech editing
  • audio diffusion
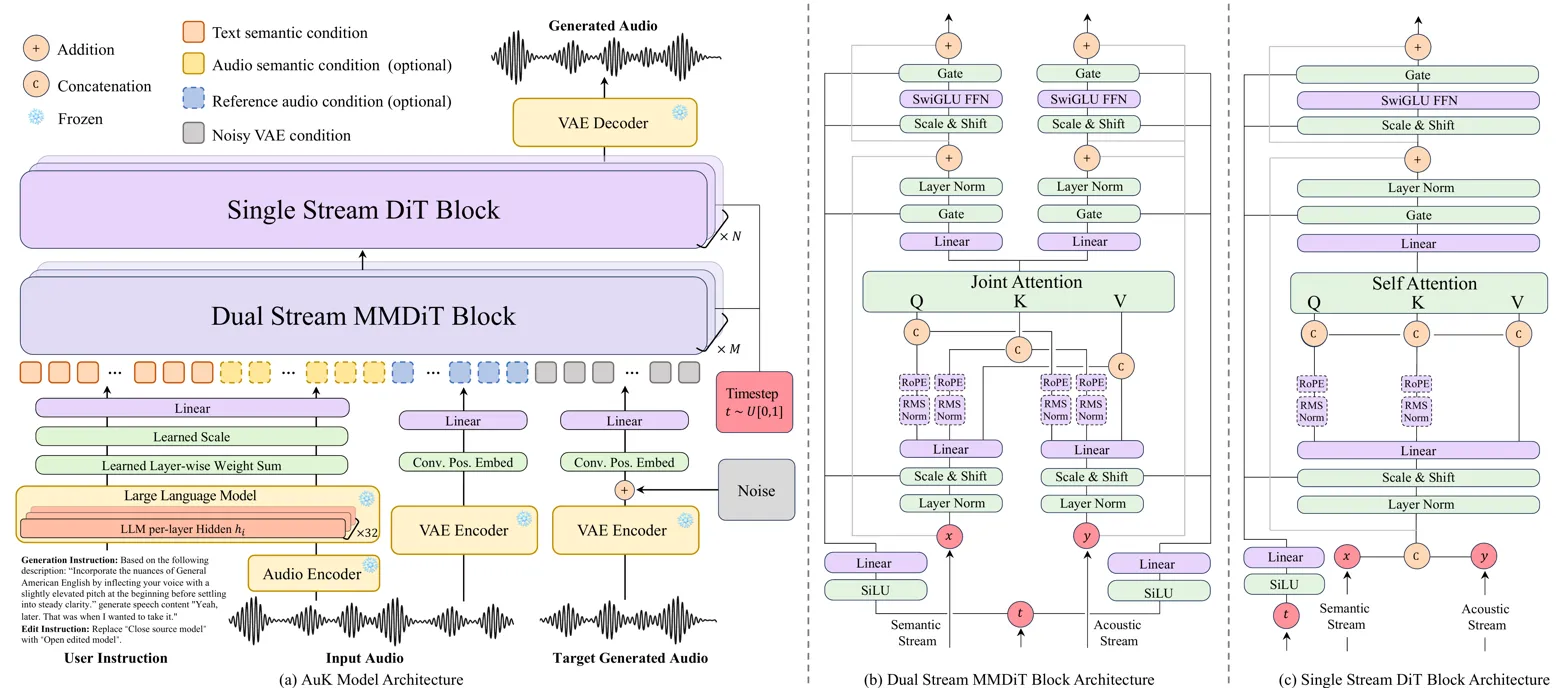
Detailed model architecture diagram showing AuK pipeline and DiT block designs

What it is

Open-source foundation model that unifies speech generation and instruction-guided editing from text and optional audio context, plus a distilled 4-step fast variant. Instead of separate task-specific speech models, one model handles generation, editing, enhancement, and separation via natural-language instructions plus optional audio context; it couples MLLM semantic conditioning with shared audio latents and a unified flow generator.

Key results

  • AuK-Flash gives 4.5× wall-clock speedup vs 32-NFE teacher
  • AuK-Flash runs in 4 steps without classifier-free guidance
  • Trained on 3.03B instruction-audio pairs and 1.95M hours

A single instruction-conditioned speech model can cover broad generation and editing tasks without giving up strong generation quality.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.