
What it is
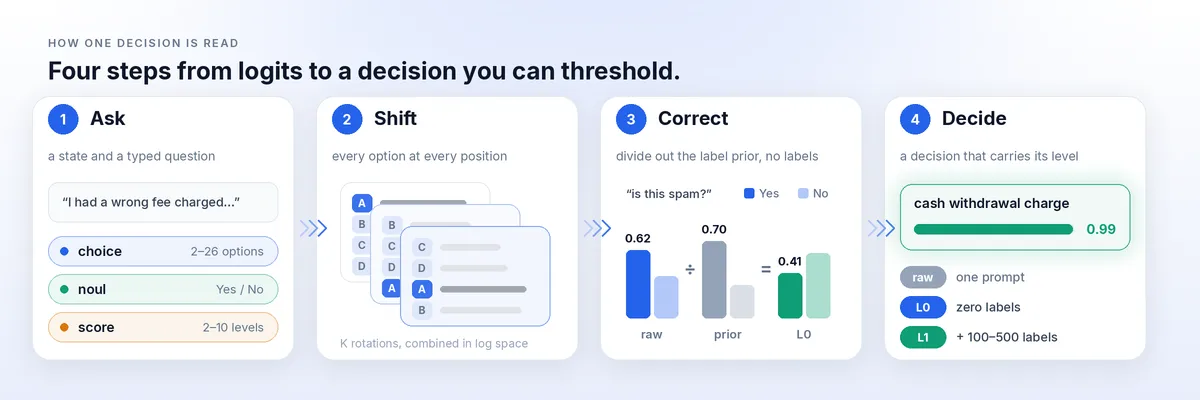
Turns open LLMs into typed decision models with thresholdable probabilities from one prefill, adding zero-label debiasing and small-label calibration or heads. Ask typed questions to an open LLM and get a discrete decision or score with usable probabilities, without generation or fine-tuning; optionally add per-question calibration or a closed-form head from 100-300 labels.
Key results
- Qwen3-8B BANKING77: auto-decidable share 7.7%→52.0% at ≤5% error
- L2 serves from one prompt stopped at ~2/3 depth; 0.68× one full forward on 8B
- Qwen3-8B typed-decisions: L0 0.647 → L2 0.771 with 300 labels/question
Shows that practical, calibrated typed decisions can be extracted from base LLMs without fine-tuning, and improved with tiny per-question heads.