Repo

uno

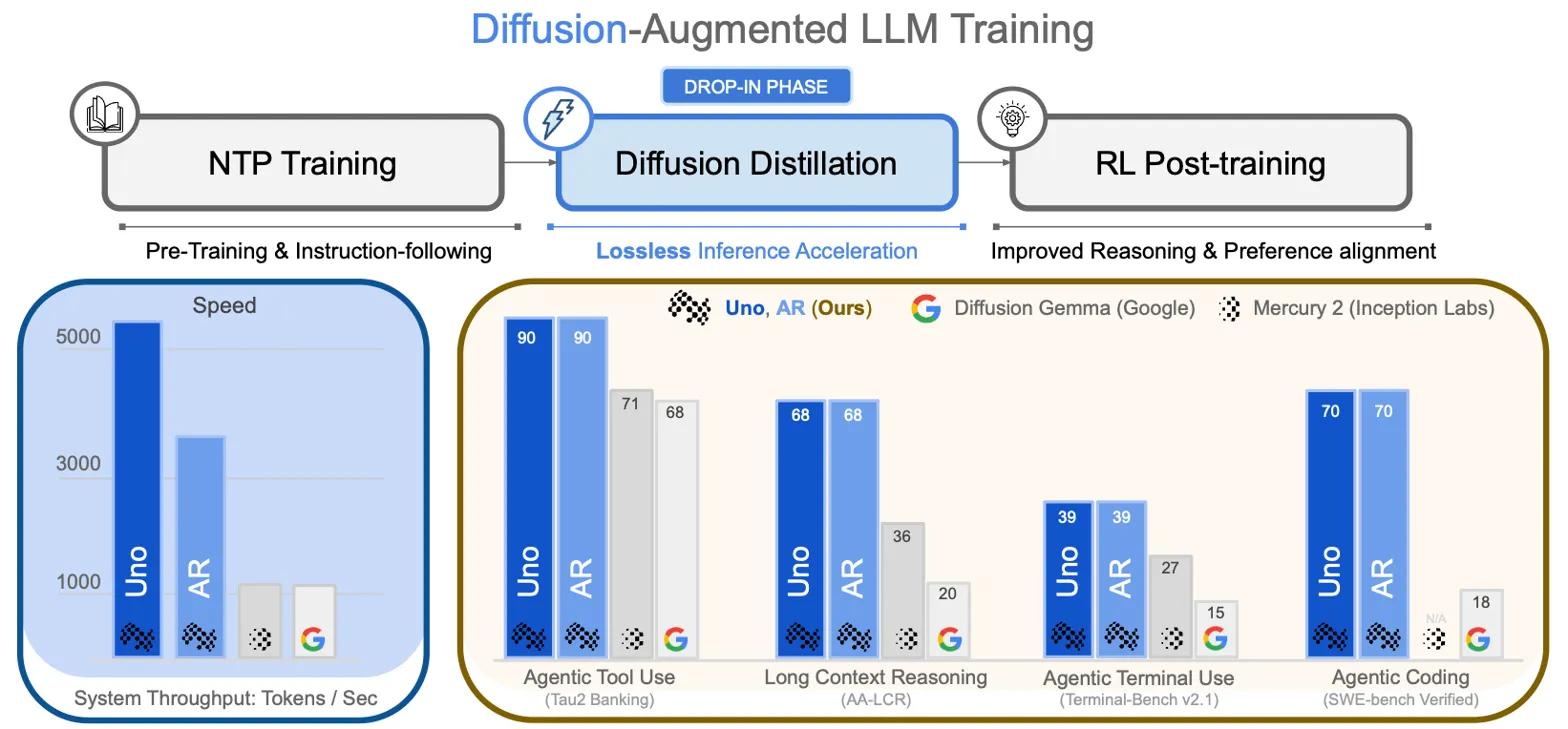
Runs lossless multi-token LLM decoding with linear or tree sampling, using diffusion weights to propose parallel tokens from the AR distribution.

GitHub ↗Sep 3, 2026Paper ↗

  • llm
  • speculative-decoding
  • discrete-diffusion
  • inference
Combines pipeline diagram with comparative benchmarks vs baselines showing core lossless acceleration claim

What it is

Discrete-diffusion LLM with a lossless multi-token sampler and a Nano-vLLM runtime for faster decoding without a separate draft model. Generate multiple tokens in parallel from an autoregressive model with a provably lossless sampler, plus ready-to-run training, inference, and evaluation workflows for Uno checkpoints.

Key results

  • Provably lossless multi-token prediction from the AR distribution
  • No separately trained draft model is required for decoding
  • Supports linear throughput mode and tree per-request throughput mode

Shows that discrete diffusion can accelerate LLM decoding while exactly preserving the base autoregressive distribution.

One useful ML email a week.

Worth your time, not all of your time.

We track new ML work across papers, code, and data, then keep only the pieces worth a closer look. Selected, not collected.

Papers.Data.Code

The Weekly ML Signal

Selected, not collected.

One useful ML email a week: the papers, repos and datasets worth your attention.

Worth your time, not all of your time.