
What it is
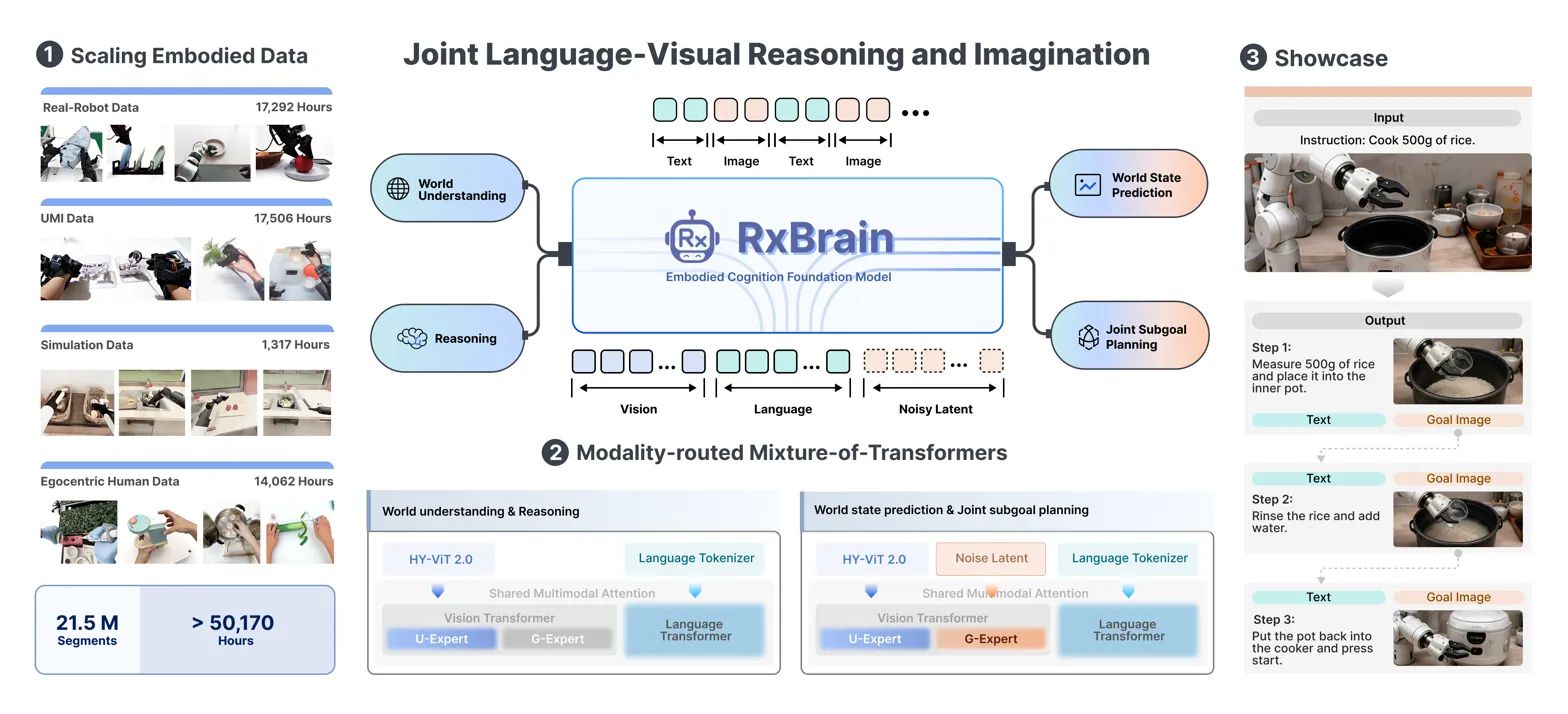
Unified embodied multimodal model for VQA, future-frame prediction, and interleaved action-plus-goal-image planning from image/video context. Answers visual questions, predicts future world states, and generates stepwise embodied plans that pair each action with an imagined goal image in one model.
Key results
- Single 6.2B model supports VQA, T2I, 4-frame rollout, and planning
- Interleaved planning emits both next action text and goal image per step
- Released inference scripts for VQA, multiframe rollout, T2I, and demos
Shows a single autoregressive multimodal model can couple embodied reasoning, visual imagination, and subgoal planning.